Repository navigation
test(managed-agent): gate R1-1 owner-release recovery across a Spring restart (FG12d) - #14990
Conversation


… restart (FG12d)

Cover #14880 item 3. During a lifecycle v2 close the Broker proxy refuses
the owner release after every configuration is drained, then the test
replaces Spring and its embedded Broker. Detach must recover with exactly
one forwarded owner release (no acquire, no MCP control), clear the
storage holder, and leave the Runtime Session RELEASED.

The recorded blocker was the rig, not WorkspaceStorageGuard:
startSpring() registered the storage and inserted the Workspace rows on
every boot, and the guard refuses a second registration while the holder
is booked. Production never re-registers on start, so seed only on the
first boot and restart in the JVM; the Broker's close writes nothing and
the durable provisioner keeps the worker alive, which is the state R1-1
needs.

R1-1 does not reproduce on main: the replaced Broker reaches the
persisted-Session release path, and #13673's managed-context branch
releases the saved Session while the Harness drains. Disabling that
branch turns the case red 3 of 3 times with the original symptom (every
retry answers 503 and the holder stays booked).

Budget the cell at 24 s (2x its measured 11.9 s): healthy 10039 -> 10063,
fork 10639 -> 10663, Verify stays 188 minutes.


|
|

|
已评审提交 重点核实了这道门禁是否真正覆盖 R1-1:
本轮实际验证(macOS arm64、JDK 21、Maven 3.9.11、Node 22.22.2、独立临时 MySQL 8.0.46,Harness 从上述提交重新构建):
验证边界:本轮没有重跑 Linux/MySQL 8.4、完整 |
|
Thanks for the PR! Template looks good ✓ — every section present, Before/After correctly marked N/A for a non-UI change, and both design-doc languages linked. Problem: observed, not theoretical — and the description keeps two distinct things straight. One is a rig defect: Direction: aligned. This closes the last open residual of #14447's FG12d row and follows the pattern the earlier cells (FG11d, FG12c, FG12d, FG13f) already established, budget ledger included. Correcting the design doc's blocker record — the rig, not the guard — is worth leaving behind on its own, and the same seeding change unblocks FG12c's split-out Spring cells. Size: not applicable, no core paths are touched. Production logic lines: 0. The 231 additions / 10 deletions are one Java IT, two design docs, the failsafe budget, a workflow comment, and the meta-test that pins that budget. Approach: the scope is the minimum the goal needs, and I checked the parts most likely to leak. The seed-once guard sits after Risk: no elevated risk signals; none of the changed files match the revert-correlated paths. One thing worth stating up front, because it changes what a green CI means here: this PR's own run selected Moving on to code review. 🔍 中文说明感谢贡献! 模板完整 ✓ —— 各节齐备,非 UI 改动的 Before/After 正确标注 N/A,设计中英文档均已附上链接。 问题: 是已观测到的,不是理论性加固——而且描述把两件事分得很清楚。一是测试 rig 的缺陷: 方向: 对齐。它收掉了 #14447 FG12d 行的最后一项残余,并沿用了既有格(FG11d、FG12c、FG12d、FG13f)已建立的模式,包括预算台账。把设计文档里的阻塞记录更正为"在 rig 而不在守卫"本身就有价值,而且同一个"只种一次"的改动也解开了 FG12c 拆出的 Spring 格。 规模: 不适用,未触及核心路径。生产逻辑行数为 0。231 增 / 10 删分布在一个 Java IT、两份设计文档、failsafe 预算、一处 workflow 注释,以及钉住该预算的 meta-test。 方案: 范围就是达成目标所需的最小集合,我重点看了最容易外溢的部分。"只种一次"的提前返回位于从新上下文重新取回 风险: 无升级风险信号;改动文件均未命中与 revert 相关的路径。 有一点需要先说明,因为它改变了"CI 绿"在这里的含义:本 PR 自己的运行选中了 进入代码审查 🔍 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
Code reviewNo critical blockers and no AGENTS.md violations. I tried to break the three things this diff actually depends on, and they hold: The seed-once guard is correctly scoped and correctly placed. The fault injection is precise, not broad. This was my main worry: the new proxy branch matches any POST whose path ends in The assertions are not vacuous. Three non-blocking notes:
I skipped the sequence diagram and the changed-files table: this is a test-only change with no product flow reshaped, and four of the six files are comment or budget updates, so a table would have said "comment updated" four times. Test evidenceThis is an unattended CI run, so I did not build or execute anything from this PR — the evidence below is the PR's own CI, read through the API for the reviewed commit. Zero checks have failed. Most lanes are green; two were still in flight at fetch time and are listed as pending rather than guessed at. The load-bearing fact is which lane is skipped. Final CI results for
One row per check name (latest run); skipped checks omitted; failures sort first. / 每个检查名一行(取最新一次运行),省略 skipped,失败项排在最前。 Bot orchestration checks (triage, review-pr, authorize, resolve-pr and friends) are omitted from the table; nothing in the full set of 55 checks reports a failure. Not verified, and why:
Sandboxed verification would settle the second gap: 中文说明代码审查没有致命阻塞项,也没有违反 AGENTS.md 的地方。我针对这个 diff 真正依赖的三点做了破坏性检查,都成立: "只种一次"的守卫作用域与位置都正确。 故障注入是精确的,不是宽泛的。 这是我主要的顾虑:新的代理分支匹配任何路径以 断言不是空转的。 三条非阻塞意见:
我省略了时序图和改动文件表:这是一个纯测试改动,没有重塑任何产品流程,而且六个文件里有四个是注释或预算更新,做成表格只会把"注释已更新"写四遍。 测试证据这是无人值守的 CI 运行,所以我没有构建或执行本 PR 的任何代码——下面的证据来自通过 API 读取的、该 PR 自己在被审 commit 上的 CI 结果。没有任何检查失败。 多数通道为绿;有两项在取数时仍在运行,如实列为 pending,不做猜测。 关键在于哪条通道被跳过。 (CI 表格见上方标记区域;机器人编排类检查已省略,全部 55 项检查中没有任何一项报失败。) 未验证的部分及原因:
沙箱验证可以补上第二个缺口: — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
|
Confidence: 4/5 — the static review is clean and I could check every load-bearing part of it; the one thing I cannot verify is structural to this repo's CI, not a defect in the PR. Stepping back: this is a well-behaved PR. It came in claiming a product regression, investigated it, found the regression does not reproduce on My independent proposal before reading the diff was: refuse the owner release at the proxy before forwarding, replace the Broker, then assert recovery with an exact wire assertion. The PR does that and goes further — I would not have thought to look at the rig's seeding as the actual blocker, and that is the contribution here over my baseline. What I verified rather than assumed: the seed-once flag is per test method (no What I could not verify, and the reason matters: this PR's run selected the fast tier, so the only job that executes The reservations I have are all non-blocking and named in the review: this addition leaves only 17 s of margin under the 188-minute step, so the next cell must raise that timeout too; the intermittent Two of the PR's own workflow runs are still in flight, so I am not posting an approval in this run. Approval is deferred until CI lands green on 中文说明Confidence: 4/5 —— 静态审查干净,其中每一个承重环节我都能核实;唯一无法验证的那一点源于本仓库 CI 的结构性安排,而不是这个 PR 的缺陷。 退一步看:这是一个规矩的 PR。它进来时声称有一个产品回归,调查之后发现该回归在 在读 diff 之前,我的独立方案是:在代理转发前拒绝 owner 释放,替换 Broker,然后用一条精确的线上断言验证恢复。这个 PR 做到了,而且走得更远——我不会想到去查 rig 的种入逻辑才是真正的阻塞点,而这正是它相对我的基线做出的贡献。 我核实而非假设的部分:那个"只种一次"的标志是按测试方法隔离的(没有 我无法核实的部分,以及原因之所以重要:本 PR 的运行选中了 fast tier,因此唯一会执行 我保留的意见都是非阻塞的,并已在审查中点名:这次新增让 188 分钟的 step 只剩 17 s 余量,所以下一个格必须同时上调那个超时;共享前导段里偶发的 该 PR 自己的 workflow 运行中还有两项在进行,所以本次不提交批准。批准推迟到 CI 在 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
…1-cell-green.png
…2-wire-503-200.png
…3-mutant-and-class.png
🔍 Local verification — PR #14990Verdict: merge-ready, with one follow-up on a pre-existing class-level race (details below). 5/5 standalone green cell runs · 3/3 mutant kills · 73/73 budget assertions · 0 checkstyle violations · 4/4 green base-class runs Verified head 🇨🇳 中文摘要结论:可以合并,但建议另开 issue 跟进一个在本机高频复现的既有类级竞态(不是本 PR 引入的)。 我在 macOS + 真实 MySQL 8.4.13 + 打包 Harness/durable worker 上完整跑通了这条新门禁:
一个需要注意的发现: 整类(9 格)在本机 7 次运行中红了 5 次,失败全部发生在共享的关闭前置( CI 提示: 因为本 PR 是 test-only, What I ran
The gate does exactly what the description claims
Finding — the shared close preamble races, and it is not rare on this hostEvery red whole-class run failed in the same place: the shared
It is not caused by this diff: the failing set includes a cell the PR does not touch, and it still appears (1 of 3 runs) with the new cell's CI caveat: for this test-only PR the hosted lane is Not covered
Methodology
Evidence captures
Verification artifacts: |
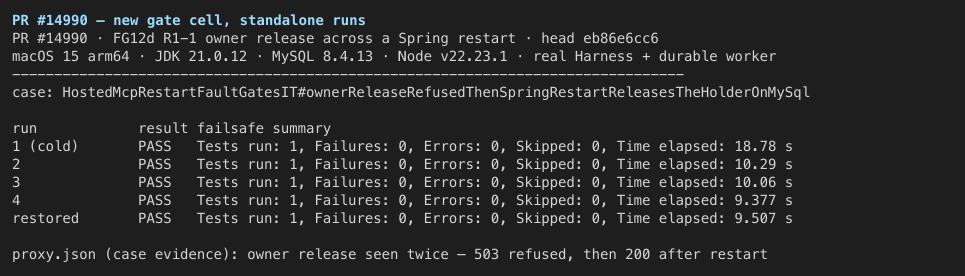
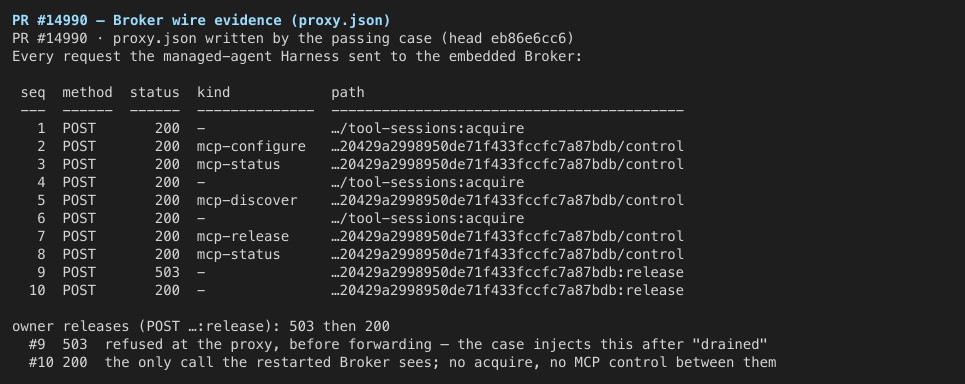
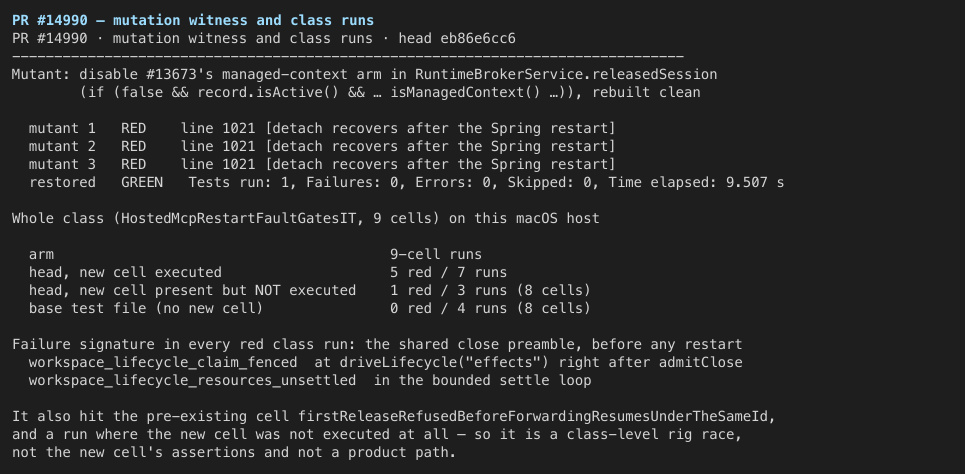
…g-restart

# Conflicts:
#	.github/workflows/sdk-java.yml
#	packages/managed-agent-server/pom.xml
#	scripts/tests/hosted-process-ci.test.js
|
I merged On the stage-2 notes:
中文说明我合并了 关于 stage 2 的几点:
|

 yiliang114
left a comment
yiliang114
left a comment
There was a problem hiding this comment.
Reviewed at 10a1494fc2.
The R1-1 cell proves the invariant rather than the happy path: the refusal is armed once through ownerReleaseRefuseArmed (CAS), the restart replaces Spring and with it the embedded Broker, and recovery is pinned by singleElement() over the proxy calls with seq > restartSeq - so "no acquire and no MCP control" is an exclusivity claim, not an absence of evidence. ownerReleaseCalls() statuses containsExactly(503, 200) supply the accumulation axis, controls("mcp-release") hasSize(1) keeps the dispatch counted once, and releaseState moving drained -> released with the storage holder going to 0 is the durable-side witness.
Two details I checked because they are the usual failure modes here:
- the injected refusal writes the same evidence fields as the pre-existing refusal branch (
status+answer), so the JSONL contract between the proxy and the Java assertions is unchanged; springSeededis what makes the restart legal - the storage registration and the Workspace rows are durable, so re-registering on the new context would be refused by the guard while the holder is booked. Re-readingjdbc/storebefore that early return is the right order.
Budget: fork 10650 -> 10674 and healthy 10050 -> 10074 (+24 = 2x the measured 11.9 s), offset 600 which is the floor, 600 + 10074 = 10674 exactly. Verify correctly stays 188 (ceil(11274/60) = 188), so ledger ['hosted-harness-mysql', 278, 291] and job 291 are right to be untouched, and the guard's "6 s left before the step must move" is accurate (188x60 - 11274 = 6). sdk-java.yml grows to 110580 bytes against the 109610 baseline - 970, inside the 4096 allowance - so not bumping .size-baseline is correct. The @Timeout count (9) matches the case-name list (9).
Merge-order note, not a finding: #14990 (+24 s) and the stacked #14991 -> #14992 -> #14993 (+150 s each) all bump the same two constants from the same base. If all four land, the terminal state is healthy 10524 / fork 11124 / Verify 196 / ledger ['hosted-harness-mysql', 286, 299] / job 299, and whoever merges last has to re-pin all five faces. The conflict is textual and fail-closed, but resolving it by keeping one side leaves every guard literal green while silently dropping the sibling's budget.

|
Released in v0.26.0. |


What this PR does
Adds the FG12d R1-1 gate cell: during a lifecycle v2 close, the owner release is refused before it reaches the Broker after every MCP configuration is
drained, and then Spring, together with its embedded Broker, is restarted. The case proves that the next detach recovers. It resends exactly one owner release, with no acquire and no MCP control. The storage holder clears, the configuration becomesreleased, and the Runtime Session becomes RELEASED.To make the restart possible, the class now seeds the storage registration and the Workspace rows only on its first Spring boot, and restarts Spring inside the JVM.
Why it's needed
#14880 item 3, the last open residual of #14447, was recorded as blocked: a whole-Spring restart "re-registers the storage" and
WorkspaceStorageGuardrefuses that while the holder is booked. That refusal came from the test rig, not from the product. The class'sstartSpring()calledregisterand inserted the Workspace rows on every boot. Production never re-registers on start:registeris the operator step (WorkspaceStorageRegistrationMain), the registration lives inma_storage_owner, and the mount roots come from configuration.R1-1 is the regression #13109's real-stack round found. After the drain receipt, a lost owner release followed by a Broker replacement left detach answering 503 forever with the holder kept, because the restarted Broker refused the release with
runtime_reconciliation_required. The retry recommended in that review never landed, so #14447 asked whether R1-1 still reproduces and planned to land a fix with the cell if it did.It does not reproduce on
main. The replaced Broker holds no local context for the Session, so the release reachesreleasedSession. The Session row is still READY, the binding is READY with the same generation, and the lifecycle v2 close has marked the Harness draining. #13673's managed-context branch in that path releases the saved Session directly. No product change is needed. The cell pins that branch.The restart happens inside the JVM rather than by killing a separate JVM. The Broker's
close()cancels in-memory work and writes nothing, and the durable local provisioner does not terminate its workers on close. The restarted Broker therefore sees the same rows and the same live worker that a killed Broker would leave behind, and that is the state R1-1 depends on.Reviewer Test Plan
How to verify
Expected: one test, zero failures. In
target/fg12-cases/fg12d/<tenant>/proxy.json, the owner release (POST …/tool-sessions/{id}:release) appears twice: first with 503 (refused before forwarding), then, after the restart, with 200 as the only call the proxy sees.Evidence (Before & After)
N/A for UI. Mutation witness: in
RuntimeBrokerService.releasedSession, disable #13673's branch (if (false && record.isActive() && … isManagedContext() …)), clean, and rerun the case. It went red 3 of 3 times at "detach recovers after the Spring restart". Every retry forwarded an owner release, the restarted Broker answered 503, and the holder stayed booked, which is the symptom #13109 recorded. The restored control, rebuilt clean, is green.Tested on
dist/cli.jsbuilt from the base:mainat7d27f475bewith a fresh install, build and bundle: the class passes 9/9 in 102.6 s, with the new case at 11.1 s.mvn -DskipTests test-compile checkstyle:check checkstyle:check@runtime-broker-checkstyleis clean on JDK 21.scripts/tests/hosted-process-ci.test.jspasses 73/73, and Prettier andgit diff --checkare clean.mainate17380e6ef(ledger conflict with test(managed-agent): reuse the run on a same-key retry (FG11d) #14981, resolved by stacking this cell on its numbers) with a fresh install, build and bundle: the class passes 9/9 in 105.4 s, with the new case at 11.3 s; the meta test passes 73/73.Environment (optional)
The packaged Harness, durable worker and real stdio fixture, as in the rest of the class. MySQL ran in a throwaway container with the binary log disabled.
Risk & Scope
workspace_lifecycle_resources_unsettledbecause the Harness writer is not active yet. That attempt sends nothing to the Broker. The bounded loop tolerates only that code andhosted_turn_active, and the wire assertion after the restart is exact (a single owner release, 200).admitClosefollowed by theeffectsphase) answeredworkspace_lifecycle_claim_fenced. The existing FG12d release cells use the same preamble. It did not recur in about 13 later runs of the preamble, and I have not root-caused it.drained(FG12c's split-out Spring cells; the seed-once change unblocks them too);main: healthy 10050 → 10074 s and fork 10650 → 10674 s. The 188-minute Verify step still wraps it (11274 s of fork plus wrap), and the job ceiling stays 291. Only 6 s of margin remain, so the step comment now says that the next cell must raise the step and the job ceiling in the same diff.Design doc: English · 中文. Both gain the same "R1-1 across a Spring restart" section, which also corrects the earlier blocker record.
Linked Issues
Part of #14447 (FG12d, the R1-1 cell). Addresses item 3 of #14880, the last open item there.
中文说明
这个 PR 做了什么
新增 FG12d 的 R1-1 门禁格:在一次 lifecycle v2 关闭中,所有 MCP configuration 都已
drained之后,owner 释放在到达 Broker 之前被拒;随后重启 Spring 及其内嵌 Broker。该格证明下一次 detach 能够恢复:它恰好重发一次 owner 释放,没有 acquire,也没有任何 MCP 控制请求。storage holder 被清空,configuration 变为released,Runtime Session 变为 RELEASED。为了能够重启,该类现在只在第一次启动 Spring 时种入 storage 登记与 Workspace 行,并在 JVM 内重启 Spring。
为什么需要
#14880 第 3 项是 #14447 最后一项未完成的残余,此前被记录为阻塞:整仓 Spring 重启会"重新登记 storage",而
WorkspaceStorageGuard在 holder 仍被占用时拒绝登记。这次拒绝来自测试 rig,而不是产品。该类的startSpring()每次启动都会调用register并插入 Workspace 行。生产环境启动时从不重新登记:register是运维步骤(WorkspaceStorageRegistrationMain),登记记录在ma_storage_owner中,挂载根来自配置。R1-1 是 #13109 真实栈轮次发现的回归。drain 回执之后,如果 owner 释放丢失、随后 Broker 被替换,detach 会永远回答 503 并保留 holder,原因是重启后的 Broker 以
runtime_reconciliation_required拒绝释放。当时评审建议的重试一直没有落地,所以 #14447 要求确认 R1-1 是否仍能复现;若仍复现,则修复与该格一起落地。它在
main上已不再复现。 被替换后的 Broker 没有该 Session 的本地上下文,所以释放请求走到releasedSession。此时 Session 行仍为 READY,binding 仍为 READY 且 generation 相同,lifecycle v2 关闭也已把 Harness 标为 draining。#13673 在这条路径上加的 managed-context 分支会直接释放已保存的 Session。因此无需改动产品代码,该格钉住的正是这个分支。重启在 JVM 内完成,而不是杀掉一个单独的 JVM。Broker 的
close()只取消内存中的工作,不写库;durable local provisioner 关闭时也不会终止 worker。因此重启后的 Broker 看到的库状态和存活 worker,与被杀掉的 Broker 留下的完全相同,而 R1-1 依赖的正是这一状态。评审测试计划
如何验证
预期:1 个测试,0 失败。在
target/fg12-cases/fg12d/<tenant>/proxy.json中,owner 释放(POST …/tool-sessions/{id}:release)出现两次:第一次为 503(在转发前被拒);重启之后为 200,并且是代理看到的唯一一次调用。证据(前后对比)
无 UI 变化。变异见证:在
RuntimeBrokerService.releasedSession中关掉 #13673 的分支(if (false && record.isActive() && … isManagedContext() …)),clean 后重跑该格。3 次运行全部在"detach 在 Spring 重启后恢复"处变红:每次重试都会转发 owner 释放,重启后的 Broker 回答 503,holder 一直被占用,正是 #13109 记录的症状。恢复并 clean 重建后的对照为绿。测试平台
dist/cli.js基于 base 构建:main的7d27f475be,经全新 install、build、bundle 后:整类 9/9 通过,用时 102.6 s,新格 11.1 s。mvn -DskipTests test-compile checkstyle:check checkstyle:check@runtime-broker-checkstyle干净。scripts/tests/hosted-process-ci.test.js73/73 通过,Prettier 与git diff --check干净。main的e17380e6ef(与 test(managed-agent): reuse the run on a same-key retry (FG11d) #14981 的账本冲突,已把本格叠加在其数字之上)并全新 install、build、bundle 后:整类 9/9 通过,用时 105.4 s,新格 11.3 s;元测试 73/73。环境(可选)
与该类其他格相同:打包 Harness、durable worker 与真实 stdio fixture。MySQL 跑在关闭 binlog 的一次性容器中。
风险与范围
workspace_lifecycle_resources_unsettled。那次尝试不会向 Broker 发送任何请求。有界循环只容忍这个错误码和hosted_turn_active,重启后的线上断言是精确的(只有一次 owner 释放,200)。admitClose之后的effects阶段)回答了workspace_lifecycle_claim_fenced。现有的 FG12d release 格使用同一段前置。之后约 13 次包含该前置的运行都没有再出现,我尚未查明根因。drained之前的 Spring 重启(FG12c 拆出的 Spring 格;"只种一次"的改动同样可以解开它们);main的基础上:healthy 10050 → 10074 s,fork 10650 → 10674 s。188 分钟的 Verify step 仍能包住(fork 加包裹共 11274 s),job 上限保持 291。余量只剩 6 s,因此 step 注释现在写明:下一个格必须在同一 diff 中同时提高该 step 与 job 上限。设计文档:English · 中文。两版都新增同一个"跨 Spring 重启的 R1-1"章节,并更正了此前关于阻塞点的记录。
关联 Issue
属于 #14447(FG12d 的 R1-1 那一格)。处理 #14880 第 3 项,也是该 issue 最后一项未完成的内容。