
Driftproof (driftproofhq): open-source agent skill evaluation and regression testing across model releases
Does your AI coding skill really help, and does the help survive a new model? Driftproof measures it and gives you a receipt.
A skill is a SKILL.md file that teaches an AI coding agent how you like things
done. Driftproof runs your skill's own test tasks with the skill and without it,
has a model score every answer several times, and tells you whether the skill
clearly helps, clearly hurts, makes no clear difference, or whether there were
too few answers to tell. Each result is a receipt: a file with the numbers that
anyone can check. Run it again when a new model comes out.
claude plugin marketplace add driftproofhq/driftproof
claude plugin install driftproof@driftproofhq
/driftproof:init on a skill you already have drafts its test cases with you,
adds them after you say yes, and makes a first receipt. /driftproof:run
measures a skill in your repository and writes its receipt. It runs on your
Claude Code subscription. You need Node.js 22 or later.
Other ways to install · Measure your own skill
Latest finding · Report 014, 7 Oct 2026: on Claude Haiku 5.5 no skill clearly helped in two or more of three repeats.

All thirteen reports · driftproofhq.com
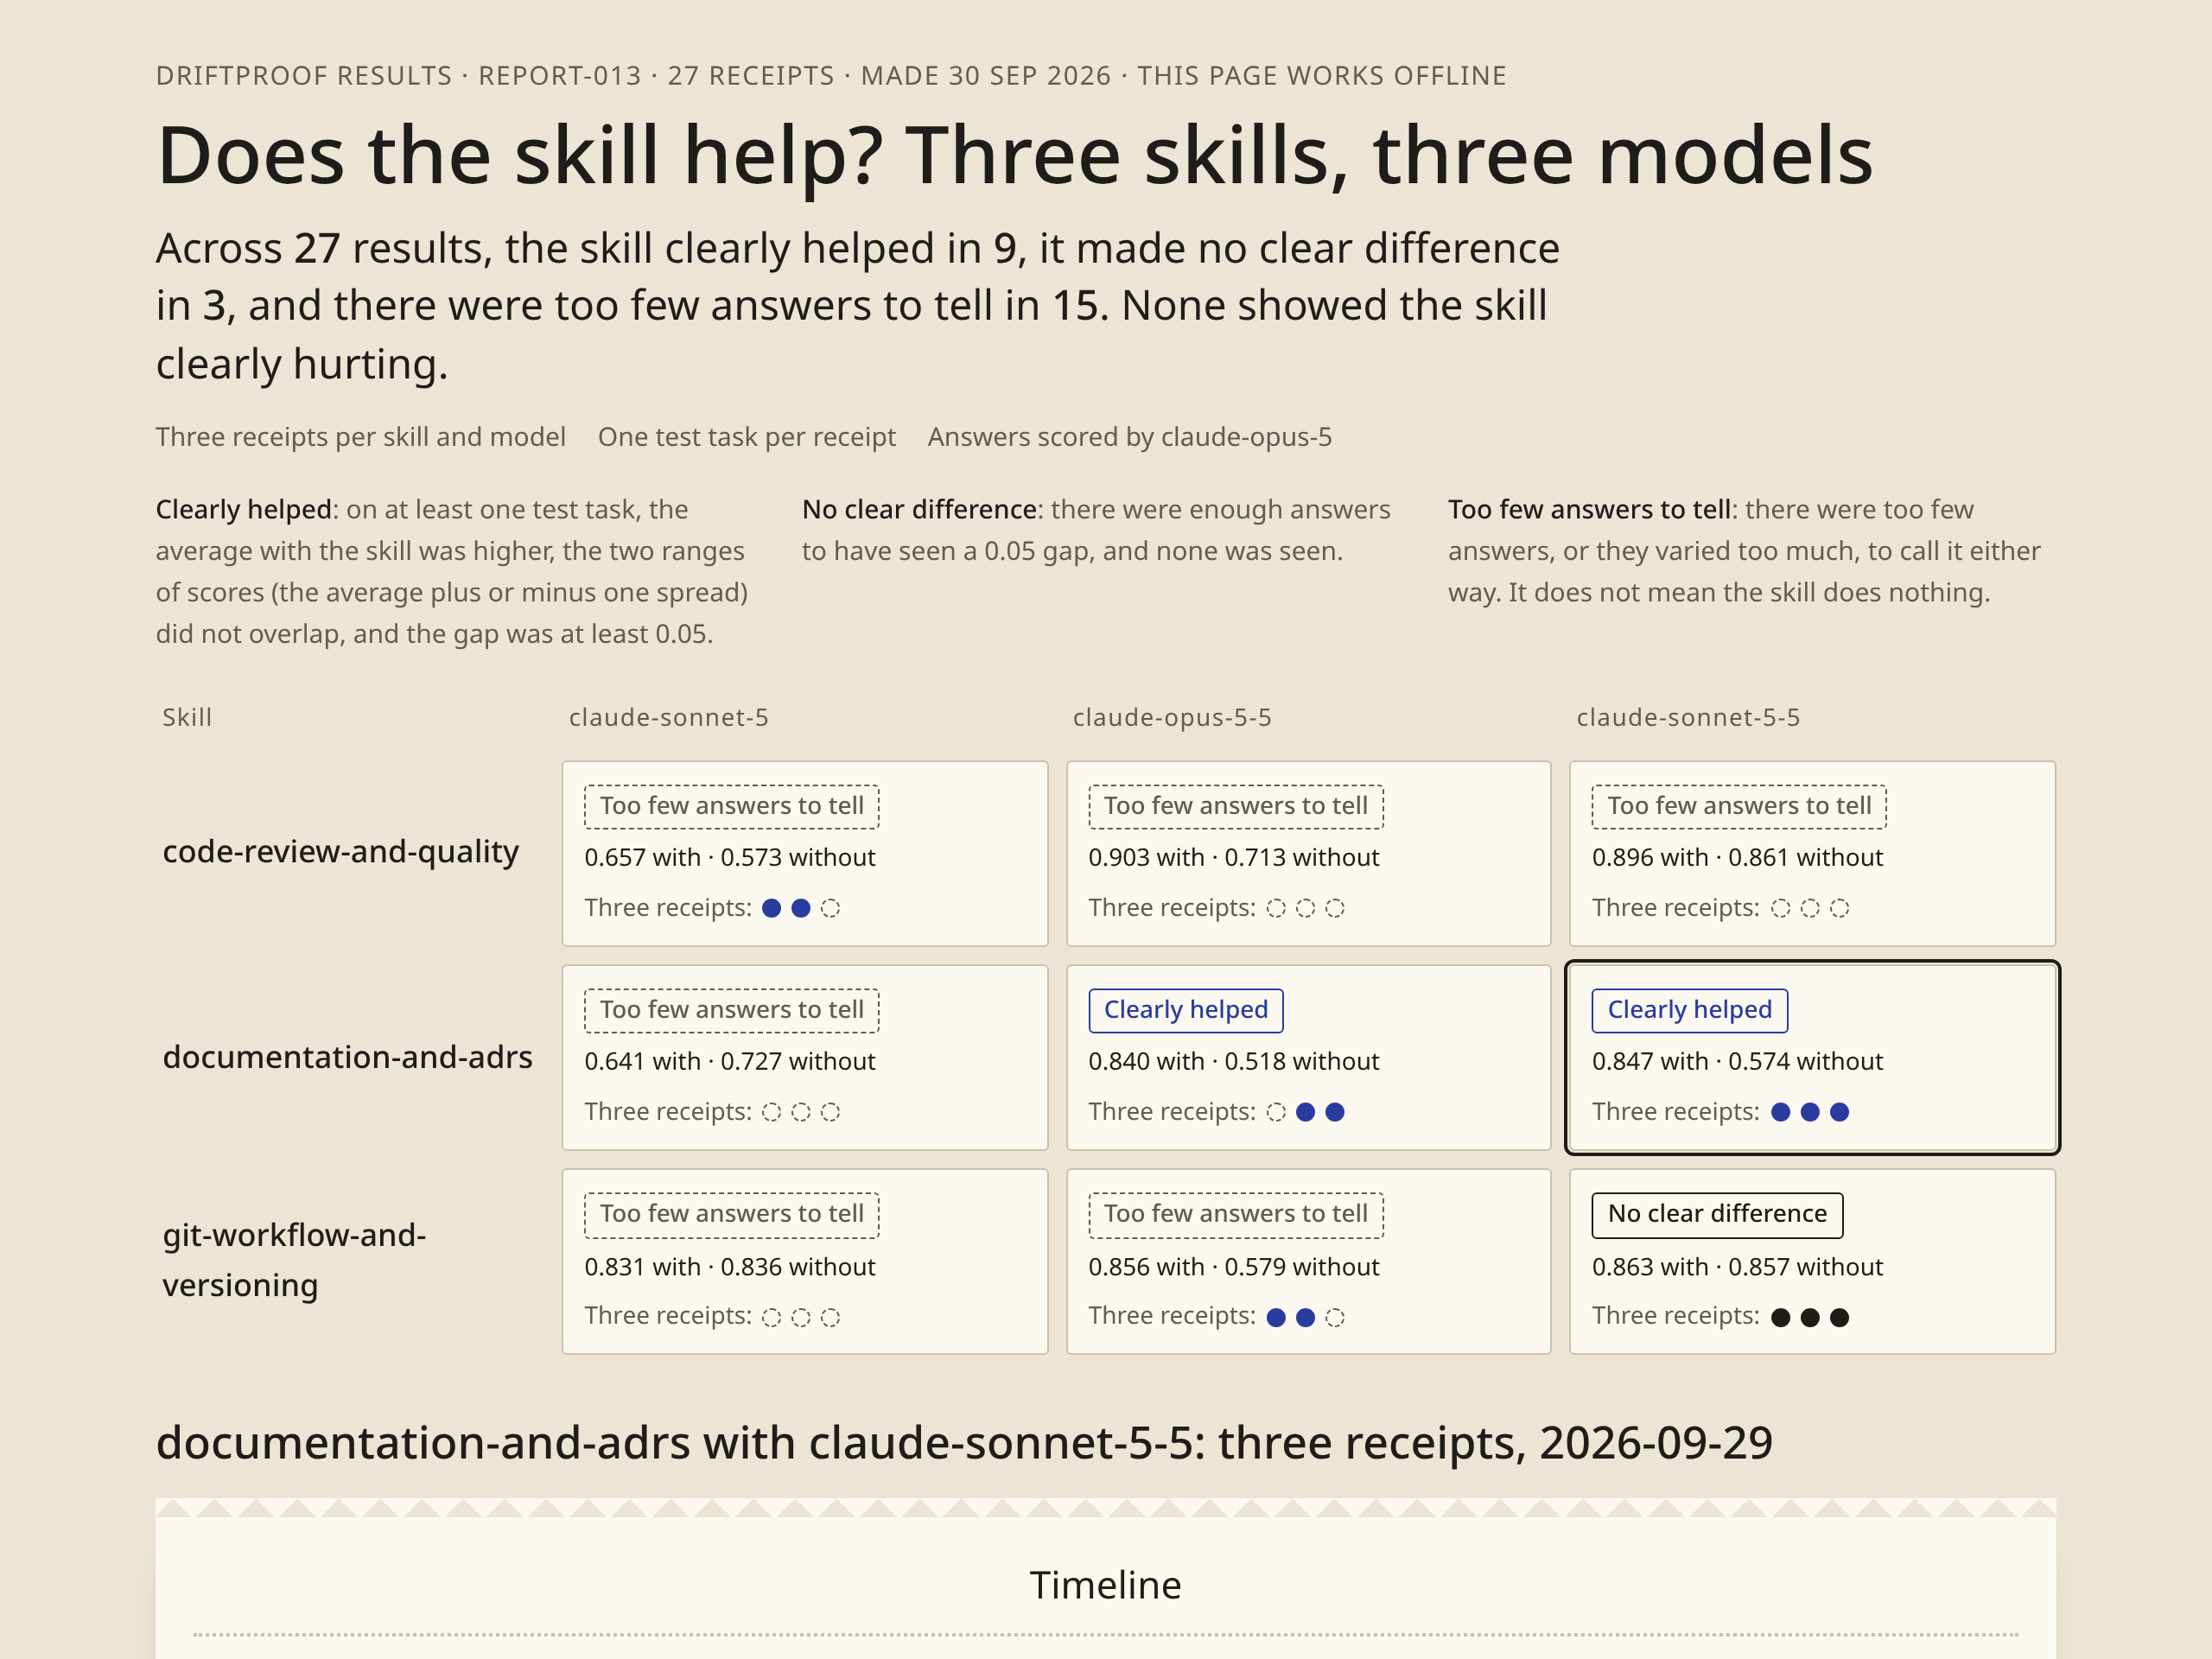
npx driftproof view makes from Report 013's
receipts,
in one file that opens from disk.
Driftproof consumes the agentskills.io/evals eval
format; it does not invent its own.
A skill is usually tested once, against one model, and the verdict is treated as permanent. But the substrate moves: models get updated, retired, and replaced. A skill that measurably helped last quarter can quietly become a no-op — or a net negative — the next time the model underneath it changes, and nobody re-checks.
Verdicts age because the substrate moves. Driftproof exists to keep the verdict current: cheap, repeatable, hash-stamped measurements bound to a specific model version, so "does this skill still help?" has a dated, verifiable answer instead of a stale one.
The hard part isn't running an eval once — it's making the number credible enough to act on. An LLM judge is noisy, so a naive score can swing run to run by more than the drift you're trying to detect. Driftproof's answer is to sample and report bands, each a descriptive spread (the mean plus or minus one sample standard deviation), and to only claim a regression when the bands don't overlap: a separation detected under that rule, not proof. A tool that cries wolf is worse than no tool.
A verdict without a price is half an answer. The same receipts price the
marginal cost of a skill firing, and Report #005 found the dominant cost driver is
not the skill's own text but the input it causes the model to pull in: across those
30 cells the input delta tracks cost at r = +0.92 while the skill's own length
tracks it at only r = +0.33, and one 738-token skill drew 34× its own size in
extra input. Identical token deltas also price very differently across substrates —
the same skill at near-identical deltas costs 3.3× more on claude-fable-5 than on
claude-sonnet-5, which is exactly their input-rate ratio in the frozen snapshot.
You need Node ≥ 22. The first path runs on your Claude Code subscription. The second
uses the command line and an ANTHROPIC_API_KEY.
Start with a skill you already have. Install the plugin (see Install), then, in Claude Code, from the folder above your skill, in a git repository:
/driftproof:init path/to/your-skill
Claude reads your SKILL.md and drafts three to five test cases with you, each aimed
at an outcome you would check in the answer. You approve them. Only after you say yes is
one new file added to the skill's folder, evals/evals.json, labelled as drafted from
the skill and approved by you. SKILL.md and every other file are left as they were.
Then it runs a quick check and opens a results page: your first receipt. A quick check
is a first look and cannot produce a verdict. /driftproof:run path/to/your-skill on a
skill with no test cases offers the same draft, and /driftproof:run without --quick
measures the skill for a verdict.
Without Claude Code, write evals/evals.json by hand (AUTHORING.md) and
go on from step 3 below.
# 1. Scaffold a skill skeleton: SKILL.md + evals/evals.json (3 example cases) + .driftproofrc
npx driftproof init my-skill

# 2. Edit the 3 example cases in my-skill/evals/evals.json so each one is grounded
#    in a claim your SKILL.md makes. Every rubric is anchored at 0.80 = "fully correct".

# 3. Point the runner at the metered API (scanner-safe: never commit a key)
export CLAUDE_PROVIDER=api
read -rsp "Anthropic API key: " ANTHROPIC_API_KEY && export ANTHROPIC_API_KEY

# 4. Run the suite. The shipped defaults (DEV_MAX_USD / DEV_MAX_CALLS in config.js)
#    refuse the run up front if the projection exceeds either; --max-usd and
#    --max-calls override them.
npx driftproof run my-skill --models claude-haiku-4-5

# 5. Read the receipt + human summary written to ./receipts/
cat receipts/*.summary.md
Reading the result. The verdict answers "does the skill still help on this
model?" — PASSED when the with-skill score beats the baseline by at least the
effect floor, NO_EFFECT when it doesn't, REGRESSED when the skill hurts. Each
case is judged several times, so it carries a band (mean ± stddev) instead of
one fragile number, and a case is only ever called regressed/improved when its two
bands don't overlap. The effect floor (0.05, one judge quantization step) is the
minimum move required before a separation is called a change: band separation
plus a floor-sized delta, never either alone.
What the band covers. Since receipt spec v0.5 a run samples the generation
as well as the judge: each arm is drawn at least 3 and at most 10 times
(GENERATION_SAMPLES_MIN and GENERATION_SAMPLES_MAX in config.js, applied by
lib/sampling.js), and each draw is judged several times. A run stops at 3 draws
when the across-draw spread is no wider than the 0.05 effect floor; otherwise it
keeps drawing until two successive estimates of that spread agree to within 0.01, or
the ceiling is reached, and each case records its stopping_reason. So a band on a
generation-sampled receipt is the spread of the model writing different responses,
not only of the judge re-scoring one. Report #006 measured that spread directly and
found it larger than judge-level noise, draw-to-draw sd 0.186 at the most, which
is why v0.5 samples it. A receipt from before v0.5 carries a legacy band, one
generation per arm re-scored by the judge, and a comparison report labels each band
(legacy) or (generation). Either way a band describes the draws a run made, at
the sample size it used, so treat a surprising verdict as worth re-running
before you act on it.
npx driftproof <cmd>        # no install — always the published version
npm install -g driftproof   # or install the CLI globally
Inside Claude Code, there is a third path — the same CLI, reached from a slash command:
claude plugin marketplace add driftproofhq/driftproof
claude plugin install driftproof@driftproofhq
That installs /driftproof:start, /driftproof:init, /driftproof:run and
/driftproof:badge.
The CLI is the product and it runs on every surface Driftproof measures, while
the plugin is one install path for Claude Code users: it builds one argument
vector, hands it to the pinned runner, and writes the receipt that runner would
have written from the same arguments. The plugin's version is the runner version
it pins, and /driftproof:run spends your Claude Code subscription rather than
an API key. It measures and never changes a skill's instructions. The one file it
adds is a new evals/evals.json, from /driftproof:start or
/driftproof:init, to a skill that has none, after you say yes in the run.
The only runtime dependency is ajv (schema validation); @anthropic-ai/sdk is
optional and pulled in only for CLAUDE_PROVIDER=api. The CLI resolves its spec,
schema, and model registry from inside the package, so it runs the same from a
global/npx install as it does in a checkout.
Platforms. Driftproof is tested on Linux and macOS. In an outside retest of
0.10.1 on macOS the shipped gate passed 592 of 611, with 19 failed and 1 not
applicable, and all nineteen failures are in the publishing helper, which needs
GNU realpath -m. Windows is untested: from Node's source the plugin would not
find npx there, but that failure has never been observed. A CI matrix across
Linux, macOS and Windows is planned.
# Diff two receipts across a model release into a drift report (markdown)
npx driftproof diff receiptA.json receiptB.json --out drift.md

# Validate a receipt against the schema + verify its self-hash
npx driftproof validate receipt.json

# Emit a shields.io badge from a receipt (see "Badge", below)
npx driftproof badge receipt.json --out badges/my-skill.json

# Interop: convert another tool's results into a DECLARED receipt (honest
# epistemics — no fabricated hashes, excluded from drift verdicts), and emit
# the minimal stable summary other tools can consume. See docs/interop.md.
npx driftproof import results.json --from agent-skills-eval   # or: skillgrade
npx driftproof import evals/results/<timestamp>/ --from claude-plugin-eval   # or: skill-creator
npx driftproof export receipt.json --to summary-json

# One self-contained HTML page from a folder of receipts: each result in plain
# words, its band plot, and whether it is up to date. It opens from disk and
# loads nothing from the network.
npx driftproof view receipts/ --out results.htmldriftproof view adds a table to each receipt sheet. driftproof diff --lift-breakdown adds separate tables for the two receipts. Without the flag, diff output stays unchanged. Each case shows the with-skill and baseline means, the sample spread across answers, their difference and the measured and lost draw counts. Downward cases are listed when their separation holds under the existing rule.
The figures use recorded draw scores and give each included case equal weight. Removing a case recomputes both arm means from the remaining cases. The table shows the resulting lift. It says a case carries the positive measured lift only when removing it leaves zero or negative lift, decided before reporting rounds the figures. This describes the retained scores, not future answers.
The breakdown is shown where evidence and eligibility permit; otherwise it states why unavailable. Legacy receipts without draw records, failed arms, incomplete evidence, contradictory counts and unlike grading cannot supply all comparative answers. Lost scores are excluded from the arithmetic and keep their existing bounds on separation. A shared lift is not attributed to a single case.
There is no model call, receipt edit or new receipt field. Existing verdicts, bands and published numbers stay unchanged. Breakdown work supports receipts up to 2 MiB, 128 cases and 64 draws per arm. Identifiers and report labels may use up to 256 UTF-8 bytes. Other strings, nesting, node count and rendered sections also have limits; unsupported evidence gets an explicit reason. These limits apply after existing receipt loading and do not bound folder traversal.
Receipts are an open format — the JSON Schema is served at its canonical id
(driftproofhq.com/spec/receipt.schema.json),
and any harness is encouraged to emit them. The interop contract (DECLARED vs
TESTED, import mappings, summary-json) is documented in
docs/interop.md and on
the interop page.
A skill directory is expected to look like:
my-skill/
  SKILL.md              # the skill instructions (required)
  evals/evals.json      # agentskills.io/evals suite (required)
  .driftproofrc         # optional run defaults (models, max_usd); samples, max_cases
                        # and judge_model are read only from the working directory's rc
                        # (the GitHub Action reads no working-directory rc at all)
  ...                   # any bundled files (contribute to content_hash)
Writing a suite that measures fairly is its own craft — see AUTHORING.md (site).
driftproof lint-suite <skill-dir> [--receipts DIR] reads the same suite as
run and prints an advisory JSON report. It runs offline, makes no model calls
and writes no receipts or verdicts. Every case appears with its evidence and a
short explanation. Findings exit 0. Invalid input exits 2; a failed receipt seal
or schema exits 4.
Prompt advice uses the longest common contiguous Unicode word run, divided by the larger prompt word count. It reports identical nonempty sequences, or at least five shared words at a ratio of 0.8 or more. Repeated words may repeat coverage. This check does not measure semantic equivalence.
Answer advice quotes supplied answer text in rubric or criterion fields, or a
field that names a possible answer. The loader can use expected as a rubric
fallback. Model exposure was not checked.
With --receipts, history requires compatible, sealed TESTED receipts for the
current skill, suite and rubric. All contributing model and judge identities
must agree. Both arms need complete measured draws with matching counts and
thresholds. Missing or contradictory evidence is reported as a notice.
Ceiling and floor findings mean no recorded pass/fail separation in these
receipts. Scores may differ; future runs may differ. Regrades are recorded
observations. A seal shows integrity since sealing, not authenticity.
Without receipts, history is explicitly not checked. No findings means these checks found none. Large inputs refuse before reporting, with named file, work or output limits. JSON strings escape controls in case names, matches and receipt filenames.
CLAUDE_PROVIDER |
surface | notes |
|---|---|---|
cli (default) |
claude-cli |
Spawns claude -p with ANTHROPIC_API_KEY stripped from the child env, so dev runs use your local subscription session. Sampling params are surface-controlled. |
api |
api |
Uses the Anthropic Messages API; requires ANTHROPIC_API_KEY and @anthropic-ai/sdk. Judge calls are pinned to temperature 0 for determinism where the surface allows it. |
The surface and judge settings used are recorded in every receipt.
A SKILL.md you did not write is instructions to an agent that has tools. On
the two cli surfaces driftproof therefore never runs claude or codex as you.
Every spawn goes through a hop to a dedicated unprivileged unix user, from an
empty environment:
/usr/bin/sudo -n -u driftproof-eval /usr/bin/env -i HOME=<its home> PATH=<its ~/.local/bin>:/usr/bin:/bin bash -lc '<wrapper>' driftproof-eval-hop claude -p ...
Only HOME and PATH reach the child, both constructed from the user name, none
copied from your shell. The working directory is a fresh temp directory made for
that one call and removed after it, including on timeout. The CLI argv is passed
as separate arguments, never as a shell string. What the evaluated agent cannot
see: your environment (tokens, keys), your home directory (SSH keys, CLI session
files), your current directory, and your CLI configuration.
Operator prerequisite, set up once. The hop is for Linux: the user's home is
/home/<name>, the path driftproof builds from the user name. That user has a
mode-700 home and no extra groups, its own logged-in claude and codex under
~/.local/bin, and a sudoers rule that lets you run commands as it, and only as
it, with NOPASSWD. DRIFTPROOF_EVAL_USER names the user (default
driftproof-eval); the name must match ^[a-z_][a-z0-9_-]{0,31}$. Without the
prerequisite a run fails at once, before any call, and says so. With the default
name:
-
Create the user with a mode-700 home and no supplementary groups:
sudo useradd -m -s /bin/bash driftproof-eval
sudo chmod 700 /home/driftproof-eval
-
As that user (
sudo -iu driftproof-eval), installclaudeandcodexunder its~/.local/bin. Then runclaudeand complete its login, and runcodex login --device-auth. Their session files live in that user's home, unreadable to your account, and yours are unreadable to it. -
Let your account run commands as that user only, with no password:
echo "$(id -un) ALL=(driftproof-eval) NOPASSWD: ALL" | sudo tee /etc/sudoers.d/driftproof-eval
sudo chmod 440 /etc/sudoers.d/driftproof-eval
sudo visudo -cf /etc/sudoers.d/driftproof-eval
-
Check the boundary by hand before the first run. From an empty environment the user's
envmust list no variable from your shell, and both CLIs must answer:H=/home/driftproof-eval; sudo -n -u driftproof-eval /usr/bin/env -i HOME=$H PATH=$H/.local/bin:/usr/bin:/bin bash -lc 'env; claude --version; codex --version'
--trusted-skill runs the legacy same-user path instead: your environment,
your cwd, your CLI login. It exists for exactly one case, a skill you authored
yourself on a machine with no eval user. Never pass it for a skill fetched from
anywhere else. The api surfaces are unaffected either way; they make HTTP calls
and spawn nothing.
Sampling multiplies calls on two axes, and the second one is easy to miss. Each
case costs SAMPLING.max × (2 + 2 × samples) model calls: two arms, each drawn
up to SAMPLING.max times (generation sampling, receipt spec v0.5), and every
draw judged samples times. Read at a single draw, that formula understates a run
by the whole draw factor — which is how the shipped caps came to sit a release
behind the estimator. Driftproof projects the whole run up front, prints the
count, and refuses before spending anything if the projection exceeds the
per-model call cap (DEV_MAX_CALLS) or the dollar budget (DEV_MAX_USD) — both
declared with their derivation in config.js, both overridable with
--max-calls / --max-usd. The default model list is haiku only.
driftproof run <skill-dir> takes three options that set how much it measures.
/driftproof:run passes --models, --max-calls, --max-usd,
--quick and these three on to run, and refuses any other option.
--quick sets these three itself, so it is refused beside any of them, in the
command and in the plugin.
| option | what it sets | default |
|---|---|---|
--samples N |
how many times the judge scores each answer | 5 |
--concurrency N |
how many case and arm pairs run at once | 1 |
--max-cases N |
run only the first N cases of the suite | every case |
Each takes a positive whole number with no leading zero. A value that is not
one is refused before a call is made, in the command and in the plugin. The
working directory's .driftproofrc can set the same three as samples,
concurrency and max_cases.
The GitHub Action reads no working-directory .driftproofrc.
A skill directory's .driftproofrc may not set
samples or max_cases; they are ignored there, with a note. When the working
directory is the skill directory, its .driftproofrc is the skill's, so
samples and max_cases are ignored there too.
While a run works it prints one line to stderr when a draw's answer has been generated, and one when all of that draw's judge calls have finished together. A line says how many calls have been made, the fewest and the most the run can make, the time so far, the time left as a range, and the case, arm and draw it has just finished:
  progress: call 1 of 18 to 60 · 4s elapsed · about 1m 08s to 3m 56s left · commit-format / with_skill draw 1: generation done
  progress: call 3 of 18 to 60 · 8s elapsed · about 40s to 2m 32s left · commit-format / with_skill draw 1: 2 judge calls done
These are example lines for a suite of one case judged twice (--samples 2);
the times are an example, not a measurement. The calls and the time left are
ranges because each arm is drawn between a fewest and a most number of times,
and the runner does not know which until the arm stops.
When the model that is being measured is also the judge, run and regrade
print a warning to stderr before any call:
  ! WARNING: the judge is the target model, claude-haiku-4-5.
  !   The model that wrote each answer also grades it.
  !   To grade with another model, pass --judge-model <id>, or set judge_model in the working directory's .driftproofrc.
The GitHub Action reads no working-directory .driftproofrc.
The warning does not stop the run. With no --judge-model and no judge_model
in the working directory's .driftproofrc, the target is the judge, so the
warning appears. /driftproof:run has no --judge-model option, so there the
.driftproofrc is how you name another judge. A skill directory's cannot name
one, and neither can the working directory's when it is the skill directory.
--capture text|files says which answer the judge sees. It can also be set as
capture in the working directory's .driftproofrc; a skill directory's is
ignored, and so is the working directory's when it is the skill directory.
The GitHub Action reads no working-directory .driftproofrc.
The default is text. /driftproof:run has no --capture option. The receipt
records the mode, and run prints it:
  answer capture: text (file-writing tools off; the reply is the answer)
  answer capture: files (the files the child wrote in its working directory are judged with its reply)
textgrades the reply. On a cli surface the child runs with no tool that writes a file or runs code. Claude is given only the toolsRead,WebFetchandWebSearch, so every other tool is off, and it loads no MCP server.codexruns in itsread-onlysandbox with the features inCODEX_TEXT_OFF(lib/capture.js, a list of the ones that write a file or run code in one codex release) switched off, and no MCP server. A feature a newer codex adds is not switched off by name.filesgrades the reply together with the files the child wrote in its own fresh working directory, for both arms. Claude is givenRead,Write,Edit,NotebookEdit,WebFetchandWebSearch, with edits accepted and no tool that runs code.codexruns in itsworkspace-writesandbox with no feature switched off, so it may run code there. After the child exits, every regular file there is named in path order. The first 50 are read, each whole when it is UTF-8 text of at most 65536 bytes, and at most 262144 bytes together. Every file not shown is named in the judged answer with its reason. Files capture needs a cli surface: on the api surface the run is refused before any call.
In either mode, an answer that points at a file the judge is not shown, or only describes work, is a lost draw and is never scored.
Run driftproof overlap <skill-dir> to report each case's longest consecutive prompt words in one bundled file, with its file and starting line. The searched bytes are the same SKILL.md and bundled files the skill loader accepts, outside evals/. Bundled receipts are searched as bytes; the command does not interpret receipts or consult receipts outside the accepted input.
Files use UTF-8 decoding with replacement for malformed bytes. A leading BOM separates words; UTF-16 is not detected. Unicode letters, combining marks and decimal digits form words. Words use NFC normalization and lowercase comparison. Punctuation and whitespace separate words. Matches may cross lines, never files. Ties use UTF-8 path byte order, then file word position, then prompt word position.
This offline command makes no model call, writes no receipt and moves no verdict. It does not prove contamination or its absence, explain measured lift, or vouch for a suite. A zero count says only that this word comparison found no shared words. Unnamed skills use the loader's directory name, so differently named aliases can change that name.
Required files must be regular. The loader bounds bundled bytes and raw suite bytes before reading. Overlap additionally refuses more than 250,000 bundled words or 1,000,000 prompt words across the suite. A refusal exits 2 with a bounded escaped reason and no report. Successful stdout is JSON with one ordered row per case, including zero results.
driftproof plan reads your full suite offline. It writes no receipt and moves
no verdict. With compatible earlier receipts, it reports conditional resolution
and hypothetical generation draw targets under the verdict's spread rule.
Spreads held. Recorded provenance must still hold, including generation and
judge surfaces, harness version, isolation and grading identity. Planning
cannot certify currentness offline. The runner may stop before any target,
even a target within its adaptive ceiling. A plan promises no next-run verdict.
Power cannot be judged until spread is measured. Start cheaply with a real smoke run, then use its receipt:
driftproof run ./my-skill --quick --models haiku --judge-model sonnet
driftproof plan ./my-skill --model haiku --judge-model sonnet --from receipt.json
driftproof plan ./my-skill --model haiku --judge-model sonnet --from receipt.json --lift 0.05 --draws 10 --samples 2
Use the same model and judge as the receipt. Repeat --from for separate
receipts. Every supplied receipt must be sealed, valid and compatible. Each
case selects the newest paired evidence by generation instant, grading instant,
then greatest receipt hash. Draws are never pooled across runs or regrades.
Missing, single or lost draws leave power unknown. Synthetic receipts are
labelled and do not measure model power. One current case left unknown keeps
the full-suite power unknown. The observed suite band stays visible; the planner
does not invent a target number of extra cases or promise that more cases help.
--samples sets judge samples per answer.
--draws sets generation draws per case per arm for the projection. It is a planner flag; run keeps its adaptive
policy. Defaults use run's built-in target, judge sample count, effect floor and
adaptive draw ceiling. Plan ignores .driftproofrc defaults and spending flags.
A requested --lift below the verdict effect floor is unsupported; more draws
cannot change that rule. Strict draw recommendations are hypothetical with
spreads held, including when the requested judge sample count differs from the
evidence. Counts that cannot be represented safely have no numeric target.
Projected calls use the same two-arm cost model as run. Only the default policy call ceiling is an upper bound for ordinary adaptive execution under that policy.
USD is a rough token-assumption cost estimate at registry API prices; actual charges can exceed it. Fixed input/output tokens per call are 3000/900 with the skill, 250/900 for baseline generation and 1300/200 for each judge sample. This is not an invoice or a subscription billing prediction. Retries and auxiliary harness calls are excluded. Long prompts can exceed the fixed token assumptions. Plan makes no provider or harness call.
A receipt is the unit of evidence — one JSON document conforming to
spec/receipt.schema.json (human companion:
spec/RECEIPT.md). Abridged, with real shape:
Key ideas:
content_hash/suite_hashare computed over a canonical JSON form, so the same skill and suite hash identically on any machine — receipts are comparable.- Per-case
samples/mean/stddevgive each case a band, a descriptive spread of one sample standard deviation. Anoutcomeofborderlinemeans the pass threshold sits inside the band — the run can't confidently call it pass or fail. delta_uncertaintyis the combined band on the with-skill-vs-baseline lift.verification_leveluses the community lattice:UNVERIFIED/DECLARED/TESTED(Driftproof emitsTESTED).FORMALis reserved.economicsis derived, never a second measurement: the token delta is the durable fact, and the dollars are exactly those tokens at the rates frozen intorun.pricing_snapshot, so a receipt keeps its meaning after a vendor reprices. Judge cost is recorded apart asjudge_usageand excluded from every skill-value figure (judge_excludedisconst true) — measuring the skill is our cost, not the skill's.receipt_hashis a self-hash for tamper-evidence (integrity, not yet a key signature; see the spec's open questions). A hash is not a signature: it does not authenticate who wrote the receipt, and it does not prove a model ran.
driftproof diff A.json B.json compares the with-skill bands per case across two
receipts. The rule that keeps it honest: a regression (or improvement) is
claimed only when the two bands do not overlap. Overlapping bands are reported
as no separation detected at the sample size used: never counted as a
regression, and never evidence that nothing changed.
Wire drift detection into a repo so the skill is re-checked on every push and when the model underneath it changes.
# .github/workflows/driftproof.yml
name: driftproof
on: [push, workflow_dispatch]
jobs:
verify:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- uses: driftproofhq/driftproof@v0.22.2
with:
skill-dir: skills/my-skill
models: claude-haiku-4-5
api-key: ${{ secrets.ANTHROPIC_API_KEY }}
# max-usd: <n> # override the dollar budget (default: DEV_MAX_USD in config.js)
# max-calls: <n> # override the per-model call cap (default: DEV_MAX_CALLS)
# fail-on-regression: 'true' # (default) fail the job on a measured regression
# fail-on-underpowered: 'false' # (default) set 'true' to fail the job on an underpowered decision
# pr-comment: 'true' # (default) on a pull request, one comment with the result in plain words
# (a requested model with no readable receipt fails the job either way)The action runs the suite on every id in models, writes one receipt per
model, uploads the whole receipt directory as a build artifact, and renders the
run on three surfaces: the badge, a job summary carrying one row per
requested model, and the check title of the enforcement step.
The checkout's .driftproofrc is not read. The action starts the run in an
empty working directory, so no key of a .driftproofrc at the repository root
is read, and a skill directory's .driftproofrc may not set max_cases,
samples or judge_model. Both files are pull-request content, and a pull
request may not narrow the run that measures it. The run takes its models and
caps from the inputs above.
The decision is taken over every receipt the run produced. Each requested
model gets one decision state, and the run's verdict is the worst of them —
worst first, in this order:
verdict |
decision state | when |
|---|---|---|
REGRESSED |
regression | measured, and the skill hurt: delta <= -EFFECT_FLOOR |
REFUSED |
refused | a requested model produced no readable receipt |
INCONCLUSIVE |
inconclusive | the run did not complete, or carries no numeric delta |
NOT_MEASURED |
not measured | the receipt is below TESTED, or nothing in it says a model answered |
UNDERPOWERED |
underpowered | measured, no separation detected in any case, and a case could not resolve the floor: Not enough draws to conclude at this effect floor |
NO_EFFECT |
no detected effect | measured, and |delta| < EFFECT_FLOOR |
PASSED |
helped | measured, and the skill helped: delta >= EFFECT_FLOOR |
So on a multi-model run a regression on any one of them governs the verdict, and the badge names the model it came from. Earlier releases decided the job from whichever receipt's filename sorted first, which is a property of the model id and not of the run — so if a Driftproof check was ever green on a multi-model run, that result was only ever about one of your models, and is worth re-running before you rely on it.
What fails the job. fail-on-regression governs regression verdicts
only: set it to 'false' and a measured regression warns instead of failing.
REFUSED is not a verdict about your skill — it is the run failing to produce
one for a model you asked for — so it fails the job whatever
fail-on-regression says. A workflow that sets fail-on-regression: 'false'
to keep the check non-blocking can still be failed this way, deliberately: a
model that was not measured did not pass. INCONCLUSIVE and NOT_MEASURED do
not fail the job on their own — a run that could not measure is not evidence that
the skill hurt — but they never render as success on any of the three
surfaces: not in the badge, not in the summary row, and not in the check title,
which carries a ::warning naming the state and the models it came from.
fail-on-underpowered governs the decisions that measured and did not
resolve, and its default is 'false': they then warn and do not fail the job.
They are every UNDERPOWERED decision, and an INCONCLUSIVE one whose reading
does not hold for every score its lost draws could have had. Set it to 'true'
and each such model fails the job with one ::error that names the model. For an
underpowered model it says how many draws per arm it would need, or that no draw
count would resolve it at its spreads, or, when draws were lost, which ones and
that no count is given. For an inconclusive model it names the lost draws. An
INCONCLUSIVE run that did not complete, and NOT_MEASURED, still do not fail
the job on their own.
A receipt set that does not say one thing is REFUSED as well. Two receipts for
one requested model, or a receipt with two rows for one case and arm, fail the job
naming the files or the case, because a decision that depends on which one was read
is not a pass. Each invocation of the Action writes to its own directory and uploads
its own artifact, so a job may run it more than once, one skill per step.
Step outputs: verdict, delta (of the model the worst decision came from),
worst_state, regressed_models, missing_models, receipts_dir and
artifact_name. Each is described in action.yml.
The pull request comment. On a pull request, the Action posts one comment
with the result in plain words and edits it on each run, so the thread holds
one comment per skill, not one per push. It is on by default; set
pr-comment: false to turn it off. It needs permissions: pull-requests: write
in the job. A pull request from a fork gets a read-only token; then, as on any
error from the GitHub API, the Action writes one notice, posts nothing, and the
run's result is unchanged. The comment never fails or blocks a run. The job
summary opens with the same sentence, above the table.
For a free CI dry-run with zero model calls, set DRIFTPROOF_STUB=1 in the job
env — the runner returns canned receipts so the wiring can be tested without spend
(this is exactly how the action's own
self-test runs). A stub receipt says what
it is: verification_level UNVERIFIED, run.surface stub,
run.answered_by.kind stub, and the verdict on it is NOT_MEASURED — it proves
the wiring, never the skill, and the badge, the summary row and the check title
all say so rather than exiting quietly green.
That self-test is also the proof behind the Action's input hardening, and it
is worth saying exactly which surface that covers. On every CI run the Action
self-test sends one hostile value through each of the Action's five inputs — a
quote, a semicolon, $(...), a backtick and a newline — on the real runner, and
the Action fails unless every one of them is refused before anything ran, so a
green check there is a claim you can read rather than one you have to take.
Those refusals live in action/lib.sh, and what they protect is the Action
surface. The CLI has carried its own input contract at its own door since
0.9.0 — the same rules, held identical to the Action's by the gate — so
npx driftproof refuses a malformed cap or model id before it projects a run.
Neither statement covers the other. Said of the Action, of CI, or of the runner, "hostile input is refused" is only ever true of the one surface it was measured on.
driftproof stale says whether each receipt's conclusion still stands under the model, harness,
capture mode, skill, suite and judge that would run today. The capture mode that would run is
--capture, else capture in the working directory's .driftproofrc, else text.
The GitHub Action that runs a suite reads no working-directory .driftproofrc.
The stale Action runs driftproof stale in the workspace, so it reads that workspace's .driftproofrc.
The staleness check runs driftproof stale on a schedule in your
repository. While any receipt needs a rerun or a regrade, one issue labelled driftproof-stale lists
each one, what moved, and the command to run next. Later runs update that issue, and the first run
that finds everything current closes it. It makes no model call and needs no API key.
Copy examples/workflows/driftproof-stale.yml into
.github/workflows/. It runs weekly and on demand, with these permissions and no others:
permissions:
contents: read
issues: write
# ...
- uses: driftproofhq/driftproof/stale@v0.22.2
with:
receipts: receipts/**/*.json
skill: skills/my-skill| Input | Default | What it does |
|---|---|---|
receipts |
receipts/**/*.json |
Glob of receipt files, one per line for several. |
skill |
none | The skill directory as it is today. Without it, the skill axis reads unknown. |
suite |
the skill's evals/evals.json |
The eval suite file. |
model, judge |
.driftproofrc |
The model and the judge that would run today. |
harness-version |
latest |
A Claude Code version, latest (read from npm), or none (not checked). |
strict |
false |
Count an unknown axis or an advisory as stale. |
fail-on-stale |
false |
Fail the job while anything is stale. |
open-issue |
true |
Keep the issue. |
issue-label |
driftproof-stale |
Give each check its own label to keep separate issues. |
github-token |
the workflow's token | Used for the issue only. |
The job fails on an error, such as a receipt that does not validate, and on stale only when
fail-on-stale is 'true'. A patch release of the harness alone (2.1.280 to 2.1.281) is an
advisory: the job summary reports it and nothing fails. An axis that cannot be known is reported as
unknown, never as current. Outputs: result (current, advisory, stale or error),
stale-count, issue-number and report-dir.
driftproof badge <receipt> emits a shields.io endpoint
JSON object. Commit it somewhere public and point a shields endpoint URL at it:
npx driftproof run skills/my-skill --models claude-haiku-4-5 --out receipts
npx driftproof badge receipts/*.json --out badges/my-skill.json
git add badges/my-skill.json && git commit -m "chore: driftproof badge"The badge at the top of this README
is the living demo: it is generated
from the commit-message-conventions example's own receipt and served from the
site, so it reflects a real dated run, not a hand-set color.
Thirteen reports are published, spanning seven report types. A report page lives at a
draft path — docs/reports/NNN-draft/ — until the publish sequence renames it, and
scripts/build-public.sh excludes every *-draft/ path from the published tree
(see the roll below, and
REPORT-STYLE.md for the shared chrome every report inherits).
Each report and every verdict in it are re-derived from the receipts committed
under receipts/
(receipts/report-001/ … receipts/report-006/) — nothing is hand-entered.
Report #010 takes no Driftproof measurement and has no receipts: it is re-derived
from the upstream harness's output files, published beside its page.
📊 Thirteen published reports (each re-derived from committed files, nothing hand-entered: Driftproof's receipts, or for Report #010 the upstream harness's own output), spanning seven published report types, the newest being instrument comparison. The twelve that measure with Driftproof read its own arms by one band-based, floor-gated verdict rule and differ in what moves underneath the skill — or, in the value report, in which axes are measured; or, in the instrument re-measurement, in the instrument itself; or, in the instrument comparison, in which instrument measures:
- Report #001 — release drift: ten public agent skills across a current-vs-previous Sonnet release; 9 of 10 showed a separation detected under the rule. (markdown)
- Report #002 — substrate durability: the same suites across two vendors' CLIs (Claude vs Codex); 3 durable, 4 substrate-dependent, 2 regressed, 1 no effect.
- Report #003 — release drift:
claude-opus-4-8→claude-opus-5; 4 improved, 2 regressed, 4 with no separation detected. - Report #004 — capability gap:
claude-opus-5(flagship) vsclaude-fable-5(frontier tier); 3 durable, 5 tier-dependent, 0 regressions, 2 no effect — encoded expertise survives the frontier tier. - Report #005 — value: what a skill
costs to run, on three axes (accuracy, cost, latency); the same ten suites on
three substrates (
claude-sonnet-5,claude-fable-5,gpt-5.6-sol) — 14 of 30 cells cleared the floor on aggregate: 10 carry a price and 4 report a saving instead, having improved quality while reducing cost. Three of those cells carry an amendment (v1.1, applied when Report #006 published): their lifts rest on single-draw baselines since shown unstable. Cause-agnostic, no corrected figures offered, and the cost-driver and substrate-disagreement findings below are unaffected. - Report #006 — revision drift: the pinned skill revision against the one upstream ships today, on a held substrate. The reuse premise was tested and refused: 3 of 3 cells returned no verdict, each blocked by its own baseline control. A 120-call probe found generation-level sampling noise 3.2× and 7.5× larger than the judge-level noise this instrument actually samples — enough to account for every gap the controls saw without any other cause being established — and the receipt spec gains generation sampling as a result. No cause is asserted; the control proves non-reproduction and cannot say why. The tally a refusal carries: 3 cells, 0 measured, 3 refused.
- Report #007 — instrument
re-measurement: the three cells Report #005 published for these skills, run
again with the generation sampled adaptively instead of once and with the call
timeout the surface policy declares. No cell separates: every lift is
smaller than its own band, and the 21 cases read 3 improved, 0 regressed,
18 no effect, 0 not measured. Five of six comparisons against the archive were
refused on their baseline control. The instrument defect it reports is its
own: a declared 300 s timeout had been shadowed by a
120000literal since 2026-07-27, and the truncated run it caused measured less variance than the clean re-run, which is the direction that flatters an instrument. Both runs are published, the broken one as evidence. Amends #005 to v1.2 and #006 to v1.1. - Report #008 — release drift:
two of Report #007's cells re-measured on
claude-fable-5-1againstclaude-fable-5, with the skillcontent_hashandsuite_hashasserted identical before the first call. Neither cell showed a separation detected under the rule: the 14 cases read 0 improved, 0 regressed, 14 with no separation detected, 0 not measured, which is not evidence that nothing changed. The first release pair in this project where both sides are generation-sampled receipts, which is what makes the delta attributable to the model rather than to the instrument. One case sits inside the verdict on the effect floor alone and the report names it. - Report #009 — instrument
comparison: three skills from one plugin, one case each, measured by Claude
Code's native plugin eval and by Driftproof on the same SKILL.md bytes, task
prompts and rubrics. The two tools apply different treatments and grade
differently, so the report reads them side by side, ranks neither, and states
what each can and cannot establish. Both tools judged with
claude-opus-5, which departs from the judge policy, so its figures are not comparable with Reports #001 to #008. - Report #010 — instrument comparison: one skill's own behavioural eval from its upstream repository, run five times under each of two Claude Code configurations at one commit: 8 passed and 2 failed, both failures on one expectation the skill's ADR instructions do not state. No Driftproof measurement was taken and no Driftproof judge ran, and the report does not isolate what caused the variation.
- Report #011 — release drift:
Claude Opus 5.5 the day after its release, measured on Report #009's three skills and
cases, one case each, beside a fresh Claude Opus 5 arm on the same Claude Code
version. Read by the runner's own comparison of the with-skill arms, the three
skills read 1 with no separation detected and 2 with not enough draws to conclude
at the effect floor, which is not evidence that nothing changed. A second table
sets Report #009's own Claude Opus 5 receipts beside this run's; between them the
Claude Code version, its host build and the date all changed. Every draw was
judged with
claude-opus-5, which departs from the judge policy, so its figures are not comparable with Reports #001 to #008. - Report #013: release drift,
Claude Sonnet 5.5 the day after its release, measured on Report #009's three skills and
cases, one case each, beside fresh Claude Sonnet 5 and Claude Opus 5.5 arms on one
Claude Code version, every arm run three times. Read by the runner's own comparison
of the with-skill arms, Claude Sonnet 5 against Claude Sonnet 5.5 across the three
runs reads 2 separated upward, 3 with no separation detected and 4 with not enough
draws to conclude at the effect floor, which is not evidence that nothing changed.
Beside Claude Opus 5.5, the rule separates Claude Sonnet 5.5 on no skill in any run,
nine results in all, and five of those nine had too few answers to tell.
Every draw was judged with
claude-opus-5, which departs from the judge policy; its figures compare with Reports #009 and #011, not with Reports #001 to #008. - Report #014: release drift,
Claude Haiku 5.5 on its release day, measured on Report #013's three skills and cases,
one case each, beside fresh Claude Haiku 4.5 arms on the same Claude Code version, every
arm run three times; Claude Sonnet 5.5 and Claude Opus 5.5 appear as Report #013's own
receipts. Each receipt is read for what the skill added to the model that answered:
documentation clearly helped Claude Haiku 4.5 in two of three runs and Claude Haiku 5.5
in none, where all three had too few answers to tell; code review and git workflow
clearly helped neither Haiku model in two of three runs. Every draw was judged with
claude-opus-5, which departs from the judge policy; its figures compare with Reports #009, #011 and #013, not with Reports #001 to #008.
✍️ The launch essay, Three model releases later: what actually happens to agent skills, reads all thirteen reports together: what moves underneath a skill, what the skill costs to run, and what a corrected instrument did to three published results. Revised 2026-10-07; every figure in it is gate-checked against the report page it cites.
Driftproof does not commit third-party skill content. Each SKILL.md is
fetched at run time from a pinned commit and verified by sha256 against
suites/manifest.json; we commit only the manifest, our
authored eval suites (suites/), the receipts, and the reports.
Reproduce Report #001 in three commands:
node scripts/fetch-skills.js # fetch pinned SKILL.md files (sha256-verified) → untracked workdir
node scripts/run-report-001.js --concurrency 5 # run both models × with/baseline, emit receipts
node scripts/build-report-001.js # re-derive the report from the receiptsReports #002–#005 have their own runners
(scripts/prepare-report-00N.js — Report #005's is
scripts/prepare-report-005.js) following the
same fetch → run → re-derive shape.
Reports are published by hand, and the release watcher is off.
scripts/release-watch.js is built to run daily from a timer
(deploy/driftproof-release-watch.timer); that timer is disabled at present, so
new model releases are not watched automatically. When the watcher runs, by
default and without a key, it compares the models a public model list names
(kept by scripts/refresh-models-cache.js) with the ones it has already seen.
That list is a third-party catalogue and can lag a vendor's own announcement by
hours; a key for the vendor's own model list takes it out of the path. The
watcher queues each new generative model for review, and marks any other new
model seen without queuing it. It then tries to prepare a draft report under TRIGGER_MAX_USD from config.js,
which needs the model registered in config/models.json and a run within that
cost limit on calls;
once a model is registered and its run fits the cost limit, that draft runs the
tests and calls the models. Registering a model and publishing a report are done
by hand, and nothing is published without review.
- A sandboxed-execution harness for tool-execution skills (document renderers, diagram/asset generators) that Report #001 scopes out.
- Signed receipts — key signatures / attestation over the canonical form
(today's
receipt_hashis tamper-evidence, not authenticity). - More import mappings — the interop wall (DECLARED vs TESTED) is built; adding a converter for another harness's results format is a small, well-marked PR (see docs/interop.md).
See CONTRIBUTING.md. The gate (npm run gate) must stay green.
{
  "schema_version": "0.13",
  "skill":  { "name": "commit-message-conventions", "version": "0.2.0",
              "content_hash": "…sha256 over SKILL.md + bundled files…" },
  "suite":  { "format": "agentskills.io/evals", "suite_hash": "…", "case_count": 10 },
  "run": {
    "model_id": "claude-haiku-4-5-20251001",
    "model_release_date": "2025-10-01",
    "provider": "anthropic",
    "surface": "claude-cli",
    "runner_version": "0.22.2",
    "date_utc": "2026-07-27T…Z",
    "registry": "registered",
    "transcripts": "hashes-only",
    "judge": { "samples": 5, "temperature": null, "sampling": "surface-controlled",
               "surface": "claude-cli", "model_id": "claude-haiku-4-5-20251001",
               "prompt_template_hash": "…sha256 over the grading template…" },
    "answered_by": { "kind": "model", "attested": true,
                     "reported_model": "claude-haiku-4-5-20251001",
                     "reported_models": ["claude-haiku-4-5"], "isolation": "eval-user" }
  },
  "results": {
    "cases": [
      { "id": "perf-not-refactor", "mode": "with_skill",
        "outcome": "pass", "score": 0.86, "mean": 0.86, "stddev": 0.05,
        "samples": [0.9, 0.8, 0.85, 0.9, 0.85],
        "judge": { "model_id": "claude-haiku-4-5-20251001", "rubric_hash": "…" } }
      // …one entry per (case, mode); baseline entries too…
    ],
    "aggregates": {
      "with_skill": { "case_count": 10, "pass_count": 7, "borderline_count": 1,
                      "mean_score": 0.81, "stddev": 0.02 },
      "baseline":   { "case_count": 10, "pass_count": 1, "mean_score": 0.42, "stddev": 0.03 }
    }
  },
  "comparison": { "with_skill_score": 0.81, "baseline_score": 0.42,
                  "delta": 0.39, "delta_uncertainty": 0.036 },
  // v0.4 economics, all derived and never composited into one score: "run.pricing_snapshot"
  // freezes the rates; each case carries "usage" and a separate "judge_usage"; "economics"
  // holds basis, surface, with_skill/baseline (call_count, mean_input_tokens,
  // mean_output_tokens, mean_cost_usd_per_call, median_wall_ms + p25/p75/IQR),
  // skill_incremental_cost_usd_per_call, skill_incremental_cost_usd_per_1k_calls,
  // output_tokens_delta, median_wall_ms_delta, judge_excluded (const true), judge_overhead.
  "verification_level": "TESTED",
  "receipt_hash": "…sha256 of the canonical receipt with this field removed…"
}