|
148 | 148 | 另外,考虑到严格达成两个奖励函数非常困难,我们还相应地提供了两个稍宽松的奖励。 |
149 | 149 |
|
150 | 150 | 1. 只要答案是一个纯数字,就给一定的奖励。 |
151 | | -2. 只要匹配到了`<think>`、`</think>`、`<answer>`和`</answer>`中的一部分,就给一定的奖励。 |
| 151 | +2. 只要匹配到了`<think>`、`</think>`、`<answer>`和`</answer>`中的一部分,就给一定的奖励,但如果匹配到多个,则扣除奖励。 |
| 152 | + |
| 153 | +奖励函数的定义详见[此文件](https://github.com/windshadow233/tiny-llm-training/blob/main/GRPO/cot_reward.py)。 |
152 | 154 |
|
153 | 155 | ### 数据处理 |
154 | 156 |
|
155 | 157 | 我们直接套用`Qwen/Qwen2.5-1.5B-Instruct`模型对应的tokenizer所提供的chat template,并定义一个系统提示词: |
156 | 158 |
|
157 | 159 | ````raw |
158 | 160 | You are given a problem. |
159 | | -Think about the problem and provide your working out. |
| 161 | +Think about it and provide your working out. |
160 | 162 | Place it between <think> and </think>. |
161 | | -Then, provide your numeric answer between <answer> and </answer>. |
| 163 | +Then, provide your numeric answer between <answer> and </answer>. For example: |
| 164 | +<think> |
| 165 | +... |
| 166 | +</think> |
| 167 | +<answer> |
| 168 | +... |
| 169 | +</answer> |
162 | 170 | ```` |
163 | 171 |
|
164 | 172 | 核心代码: |
@@ -203,26 +211,42 @@ def __getitem__(self, idx): |
203 | 211 |
|
204 | 212 | 训练曲线: |
205 | 213 |
|
206 | | -<img src="https://blogfiles.oss.fyz666.xyz/png/576c7496-2fd9-478d-b5d6-2b4d51f5faf1.png" style="zoom:50%;" /> |
| 214 | +<img src="https://blogfiles.oss.fyz666.xyz/png/cd33ab82-0cc9-4a4b-ad91-9f80638526d9.png" style="zoom:50%;" /> |
| 215 | + |
| 216 | +注意到总体 Reward 还是在上升的,并且我们还分别记录观察了三个独立的Reward函数的变化趋势,发现模型在准确率、格式方面都有所提升,唯独这个Soft Format在上升到一定程度后有所下降,观察到模型有时会重复输出answer的闭合tag:`</answer>`,目前还不知道是什么原因(明明给了一定的惩罚?)。 |
207 | 217 |
|
208 | | -注意到 Reward 还是在上升的。另外,每隔10次迭代,打印一下模型生成的结果,发现模型确实在准确率方面有所提升,另外在格式上也有所对齐。下面先贴出几个例子,在测试集上的评测结果待日后再补充。 |
| 218 | +另外,每隔10次迭代,打印了一下模型生成的结果,发现模型确实能做对一些题,并且在格式上也有所对齐,思考过程有模有样。下面贴出几个例子。 |
209 | 219 |
|
210 | 220 | {% gallery %} |
211 | 221 |
|
212 | | - |
213 | | - |
214 | | - |
| 222 | +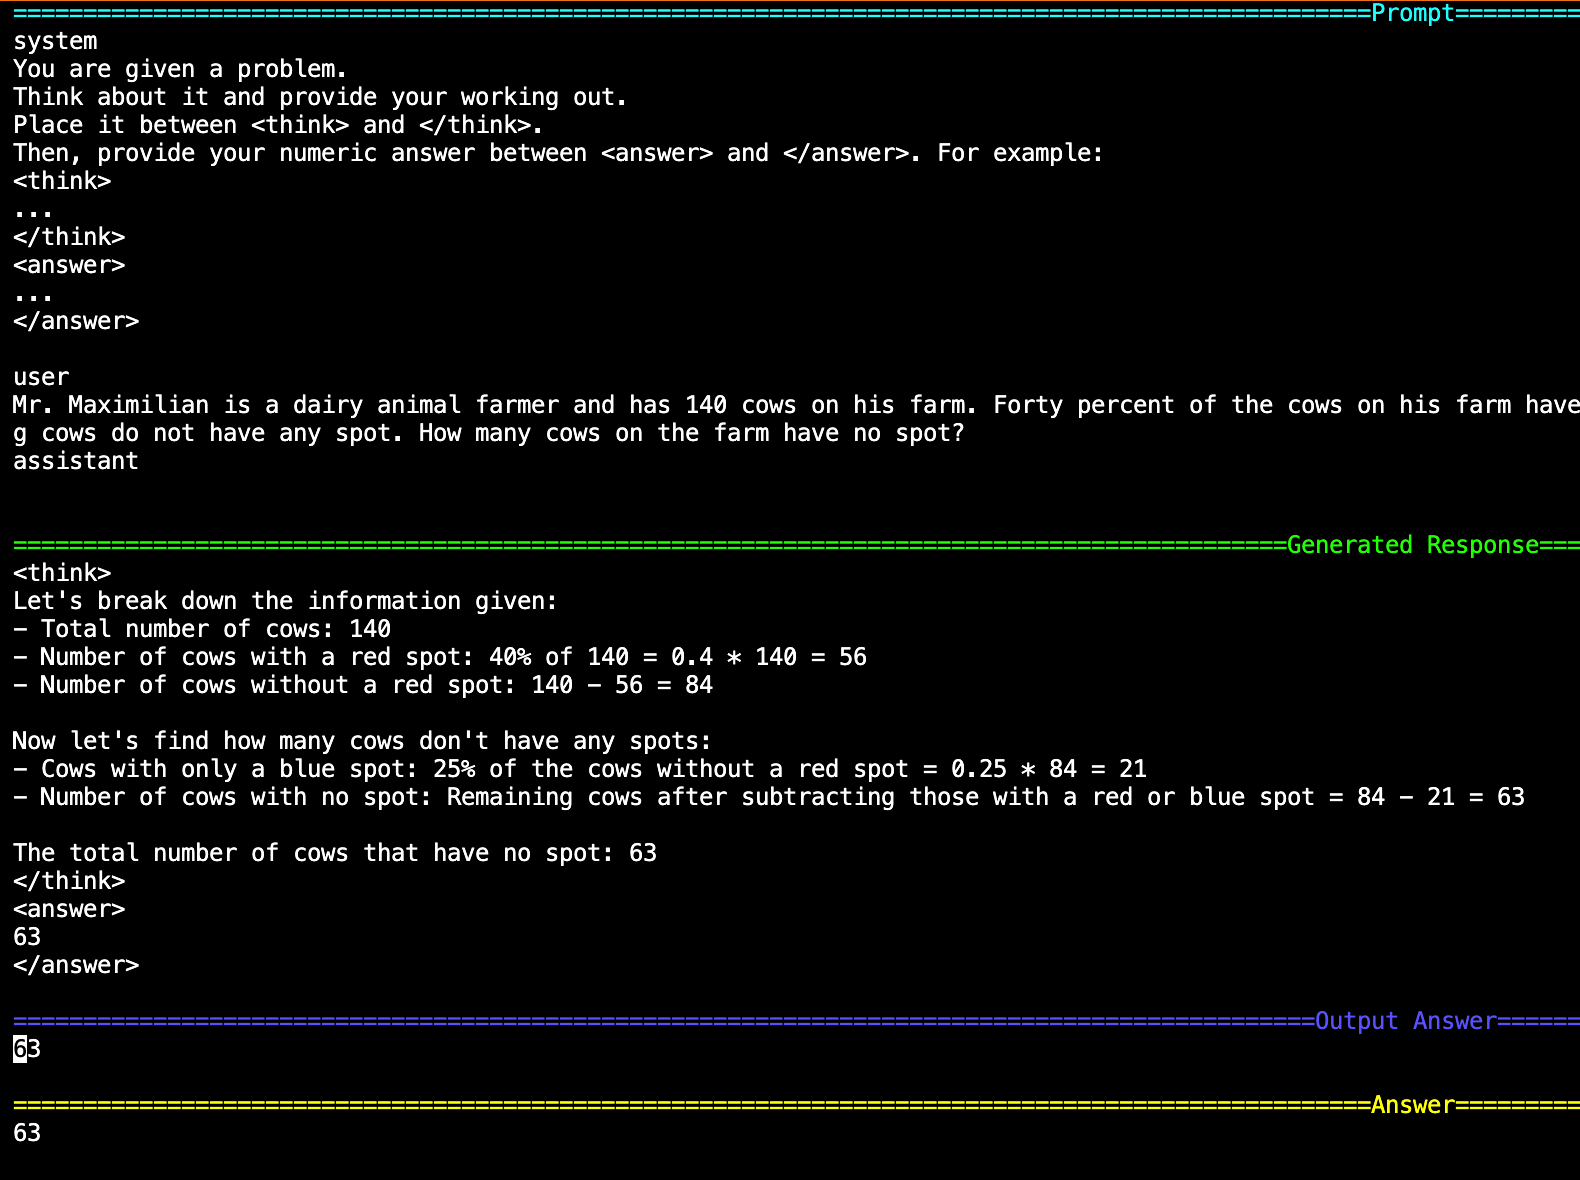 |
| 223 | + |
| 224 | +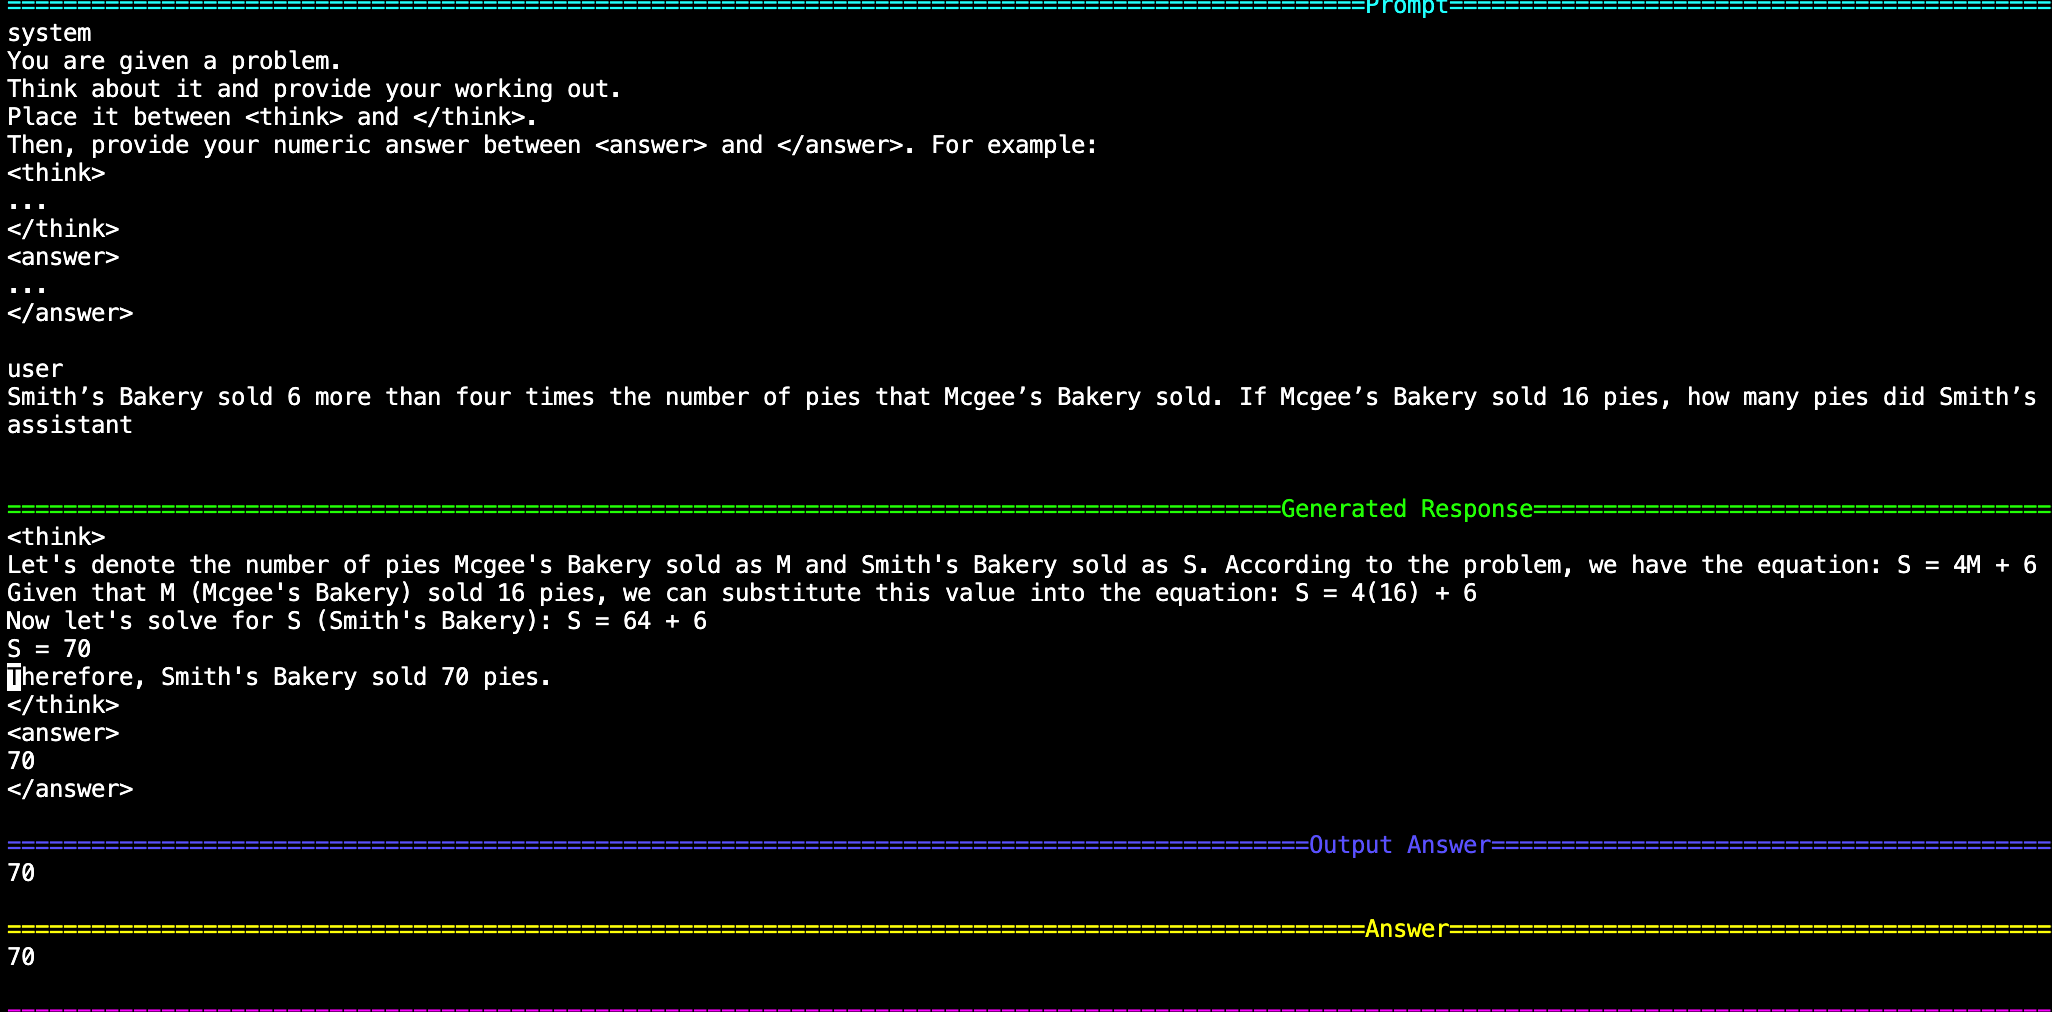 |
| 225 | + |
| 226 | +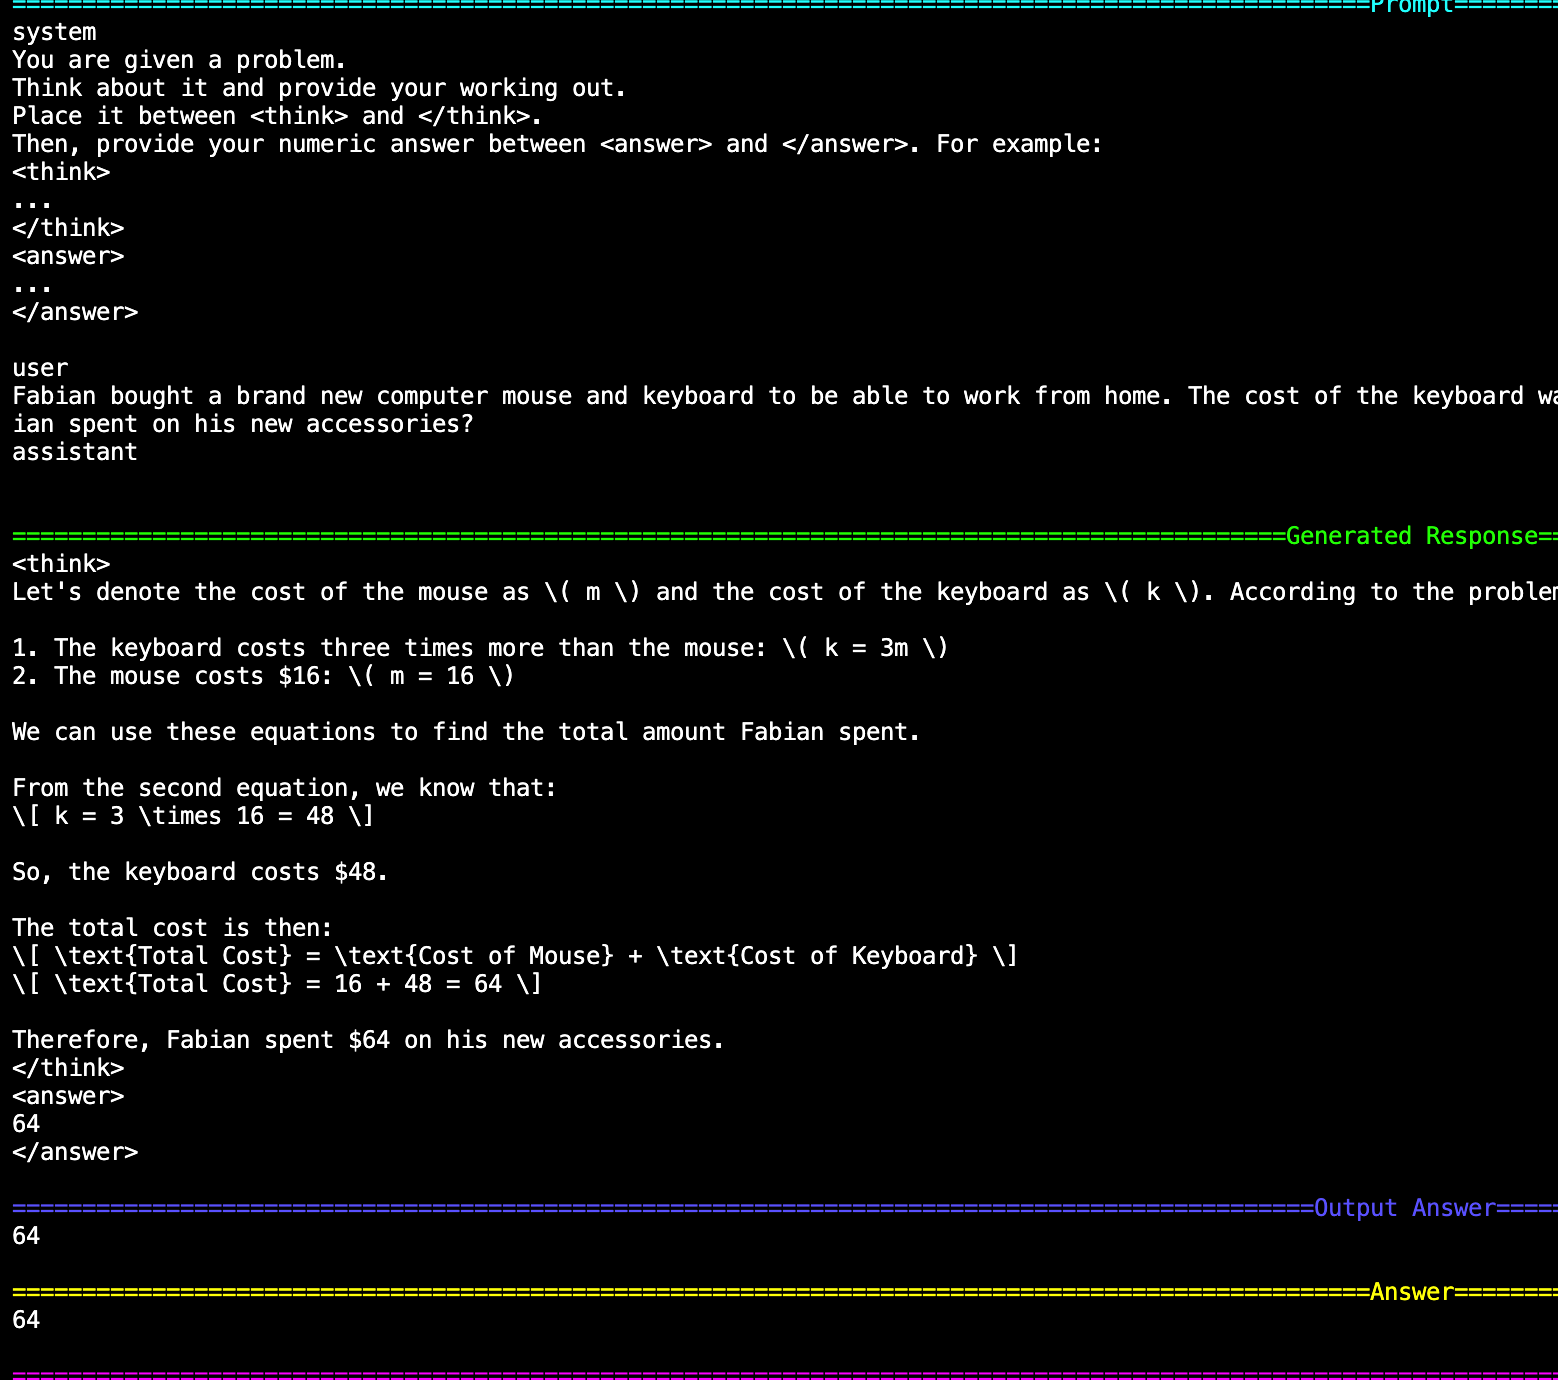 |
| 227 | + |
| 228 | +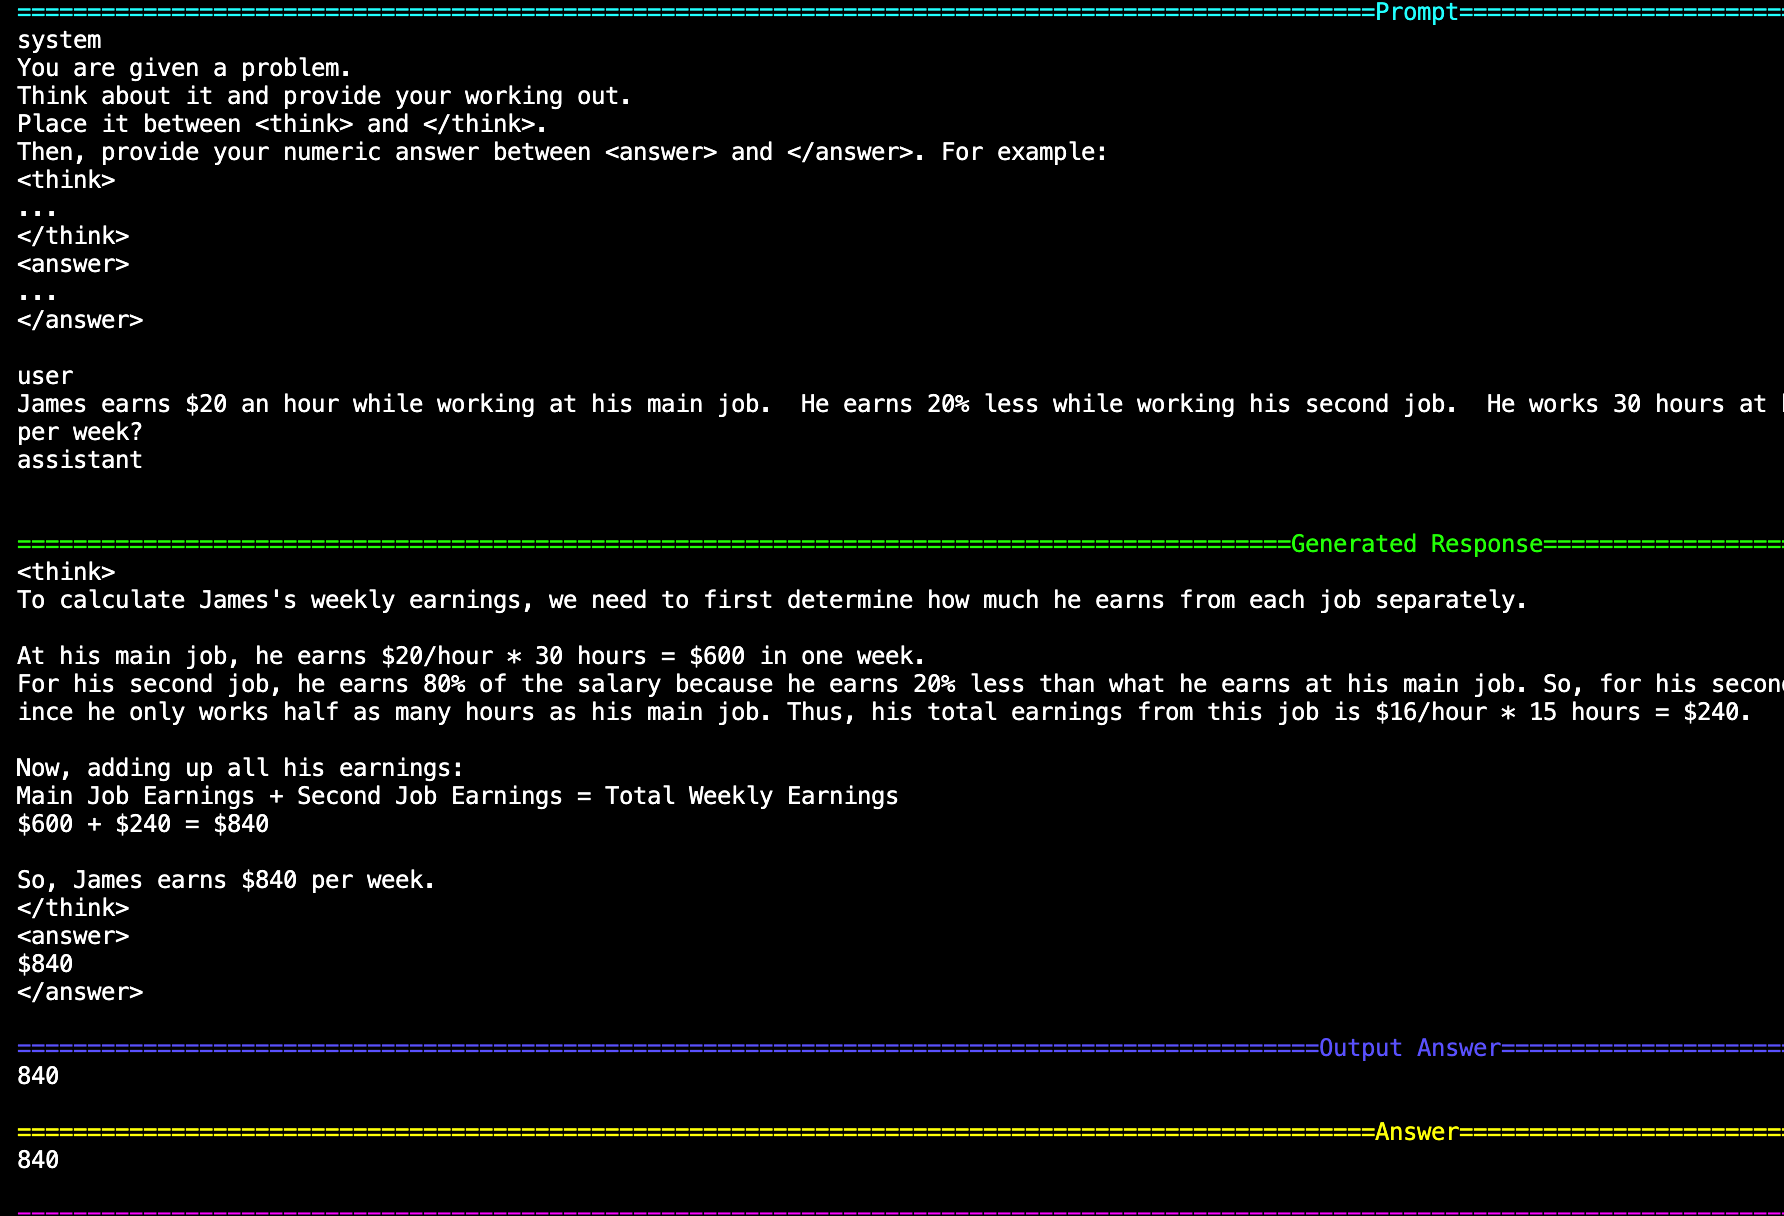 |
215 | 229 |
|
216 | 230 | {% endgallery %} |
217 | 231 |
|
| 232 | +最终,博主将迭代了400个step的模型与未训了的初始模型进行了测试与对比,结果如下: |
| 233 | + |
| 234 | +```raw |
| 235 | +Qwen Accuracy: 0.4314 Formatted: 0.6088 GRPO Accuracy: 0.5610 Formatted: 0.9121 |
| 236 | +``` |
| 237 | + |
| 238 | +可见经过GRPO迭代的模型已经具备了较强的格式对齐能力,在准确率方面也有了一定的提升,意味着训练还是有一定的效果的。 |
| 239 | + |
218 | 240 | --- |
219 | 241 |
|
220 | | -本文相关代码**将**开源于下面仓库: |
| 242 | +本文相关代码已开源于下面仓库: |
221 | 243 |
|
222 | 244 | {% link tiny-llm-training, GitHub, https://github.com/windshadow233/tiny-llm-training/ %} |
223 | 245 |
|
224 | 246 | {% note warning %} |
225 | 247 |
|
226 | | -由于实验中途突然被抓去跑了一些别的东西,只好先把实验停了,在无法确保实验最终效果的情况下,尚未开源本文代码,敬请期待! |
| 248 | +~~由于实验中途突然被抓去跑了一些别的东西,只好先把实验停了,在无法确保实验最终效果的情况下,尚未开源本文代码,敬请期待!~~ |
| 249 | + |
| 250 | +只是实现了一个微小的demo,在细节方面仍有所欠缺,有待进一步斟酌,希望大佬们不吝赐教! |
227 | 251 |
|
228 | 252 | {% endnote %} |

0 commit comments